machine learning, ai, cs · slides

Paper overview | Deep Residual Learning for Image Recognition
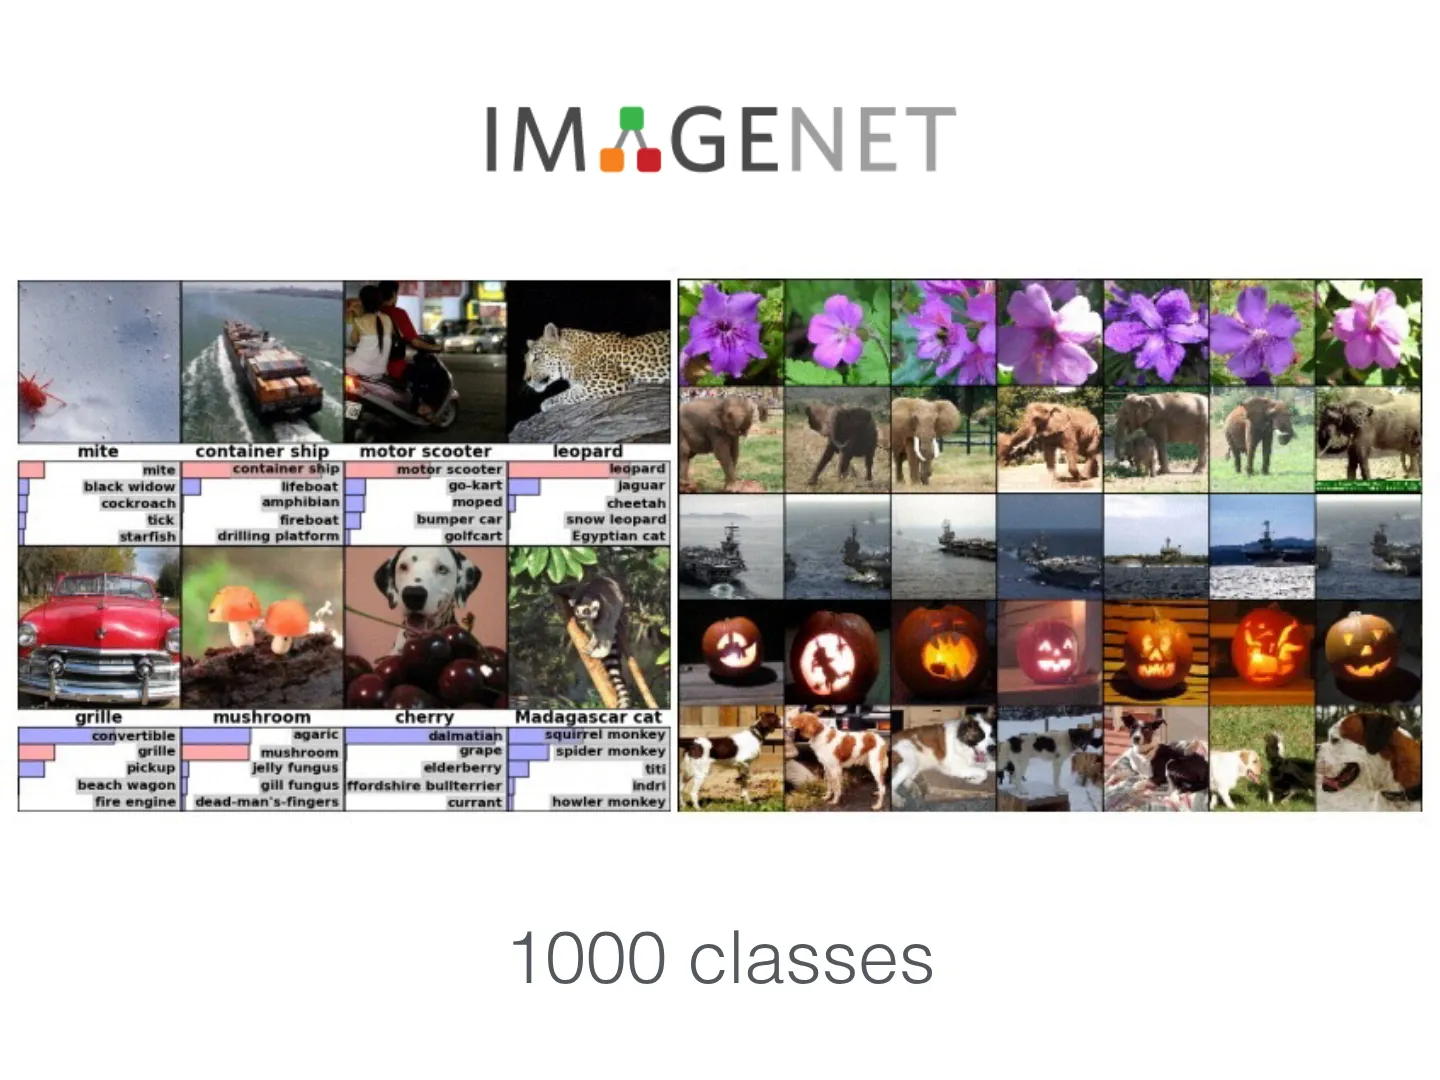
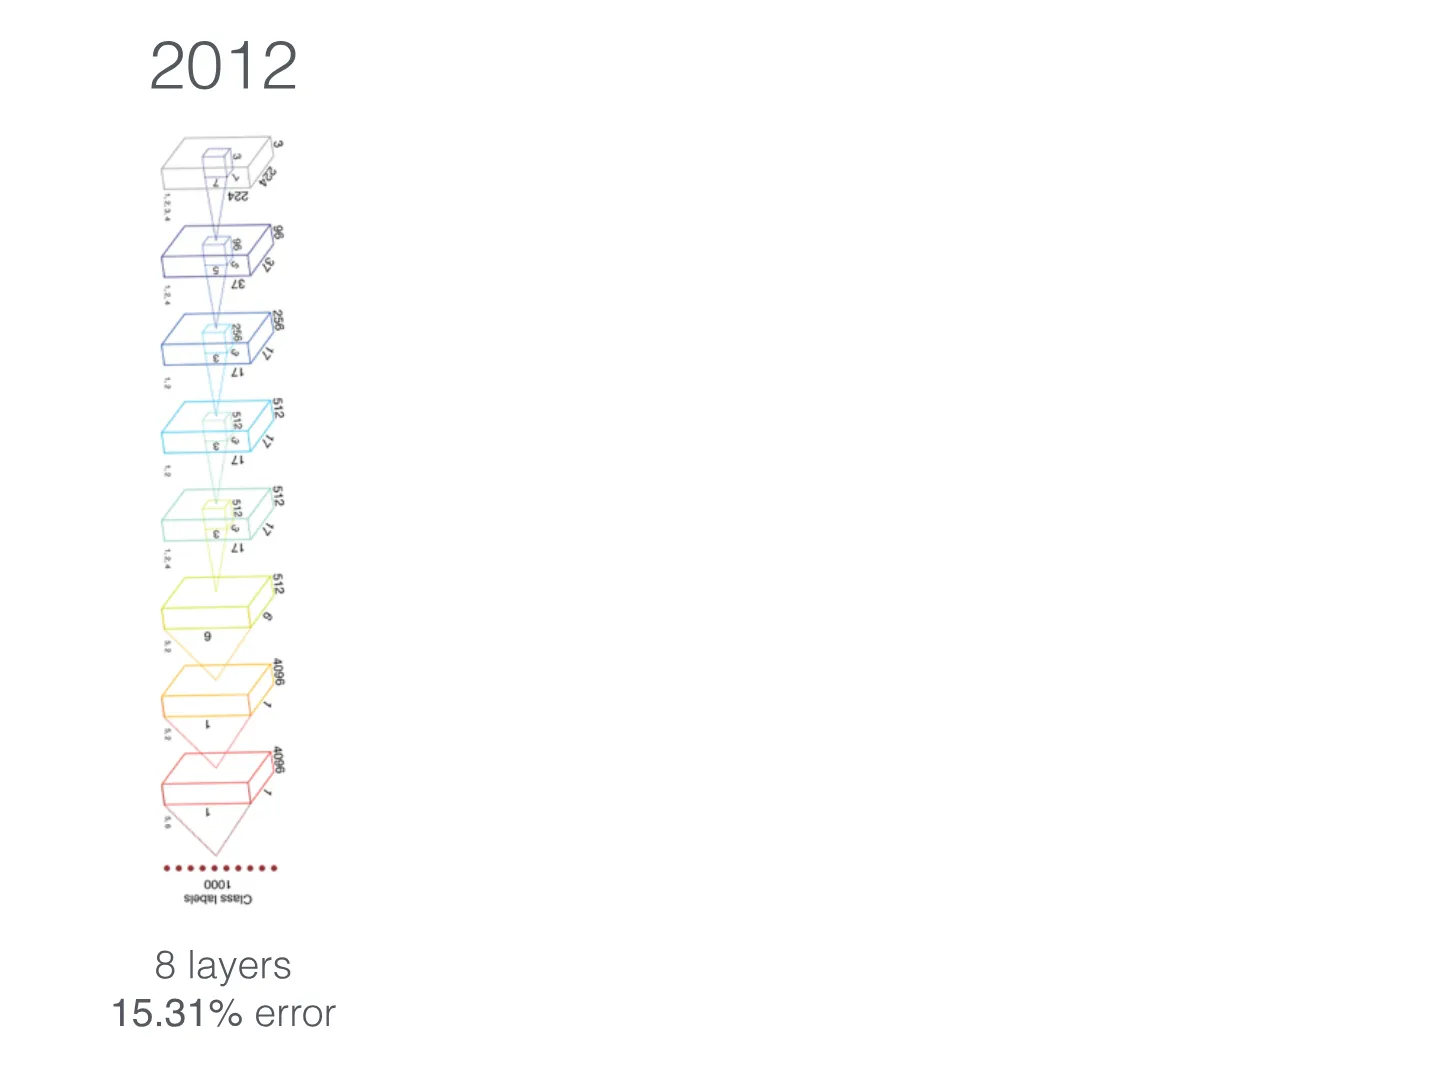
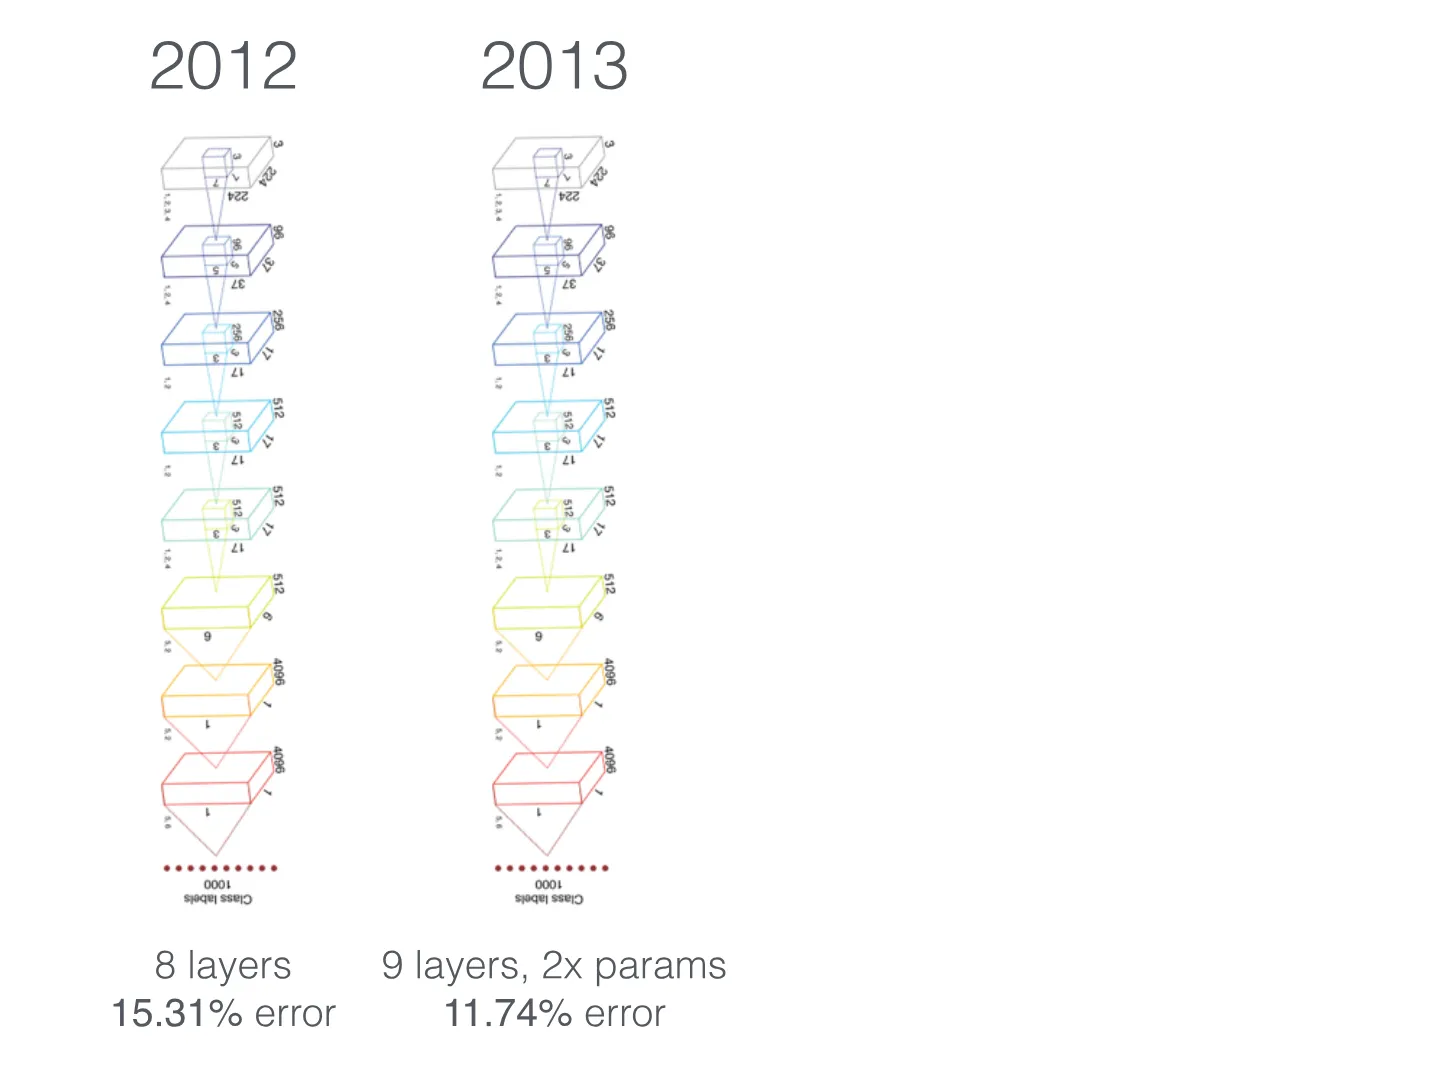
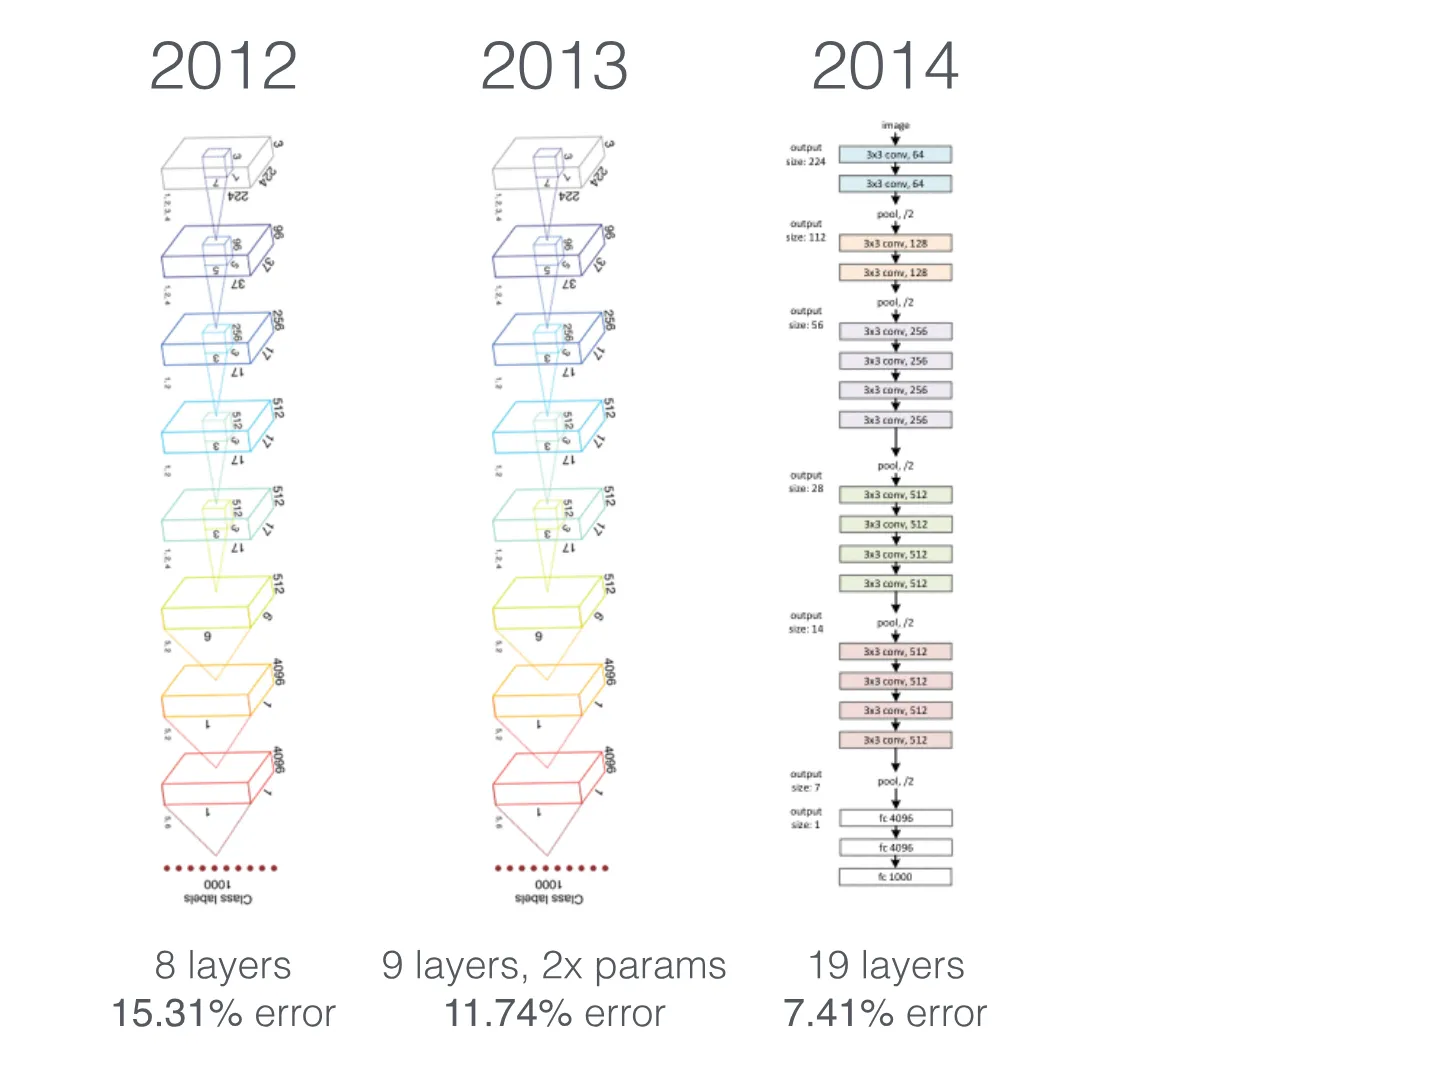
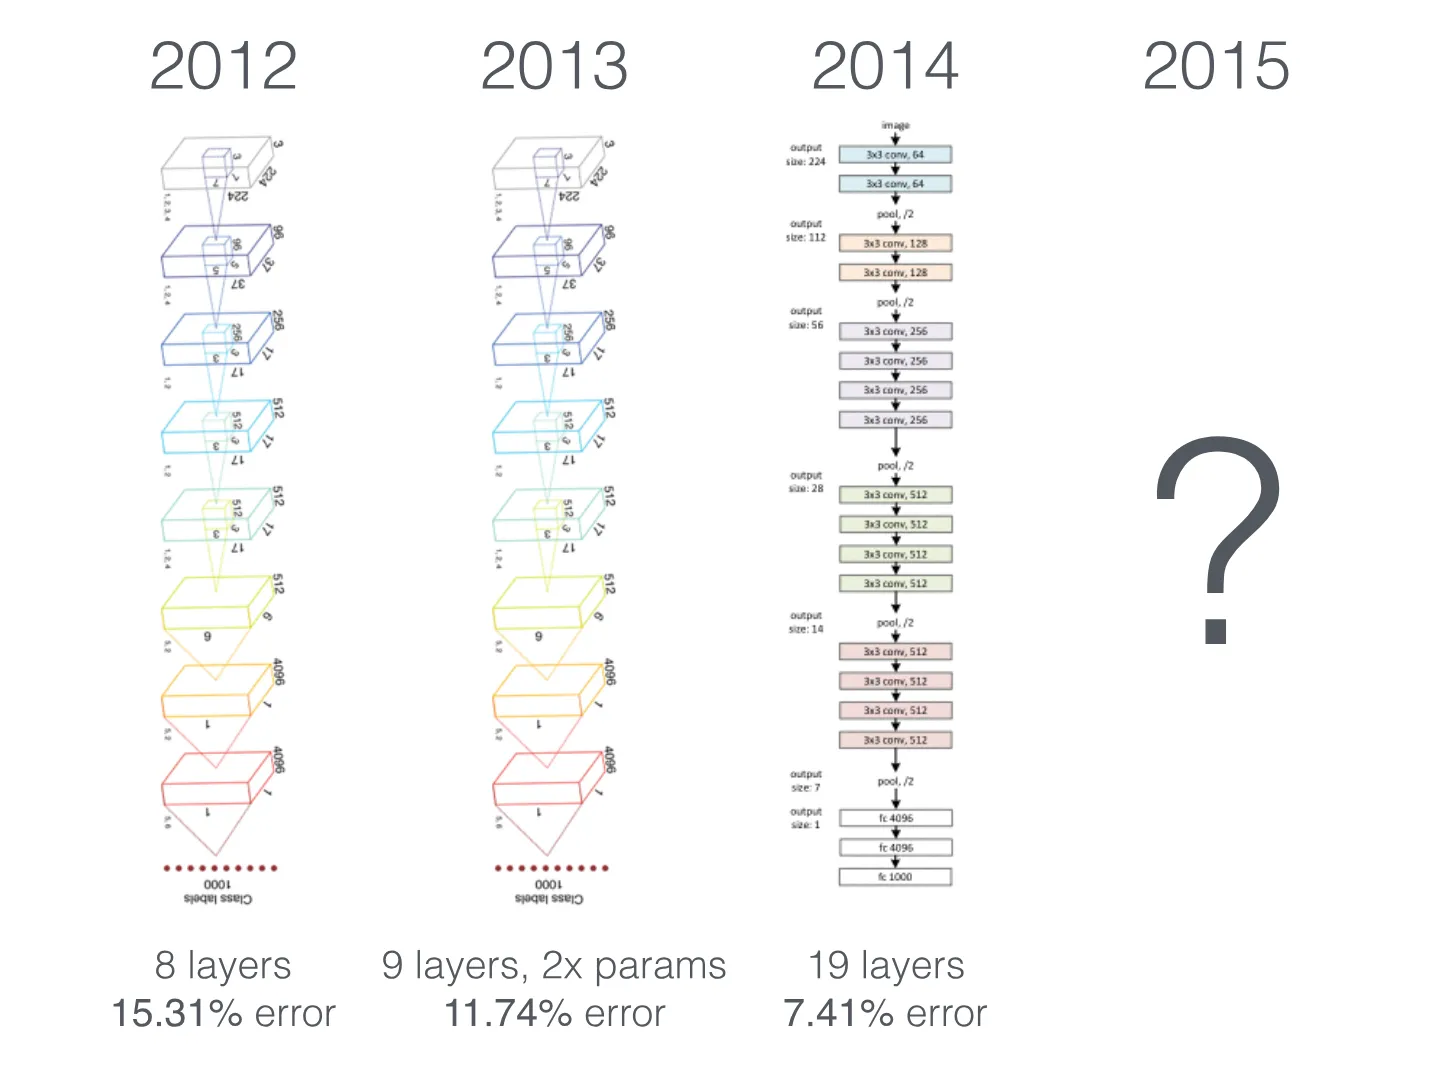
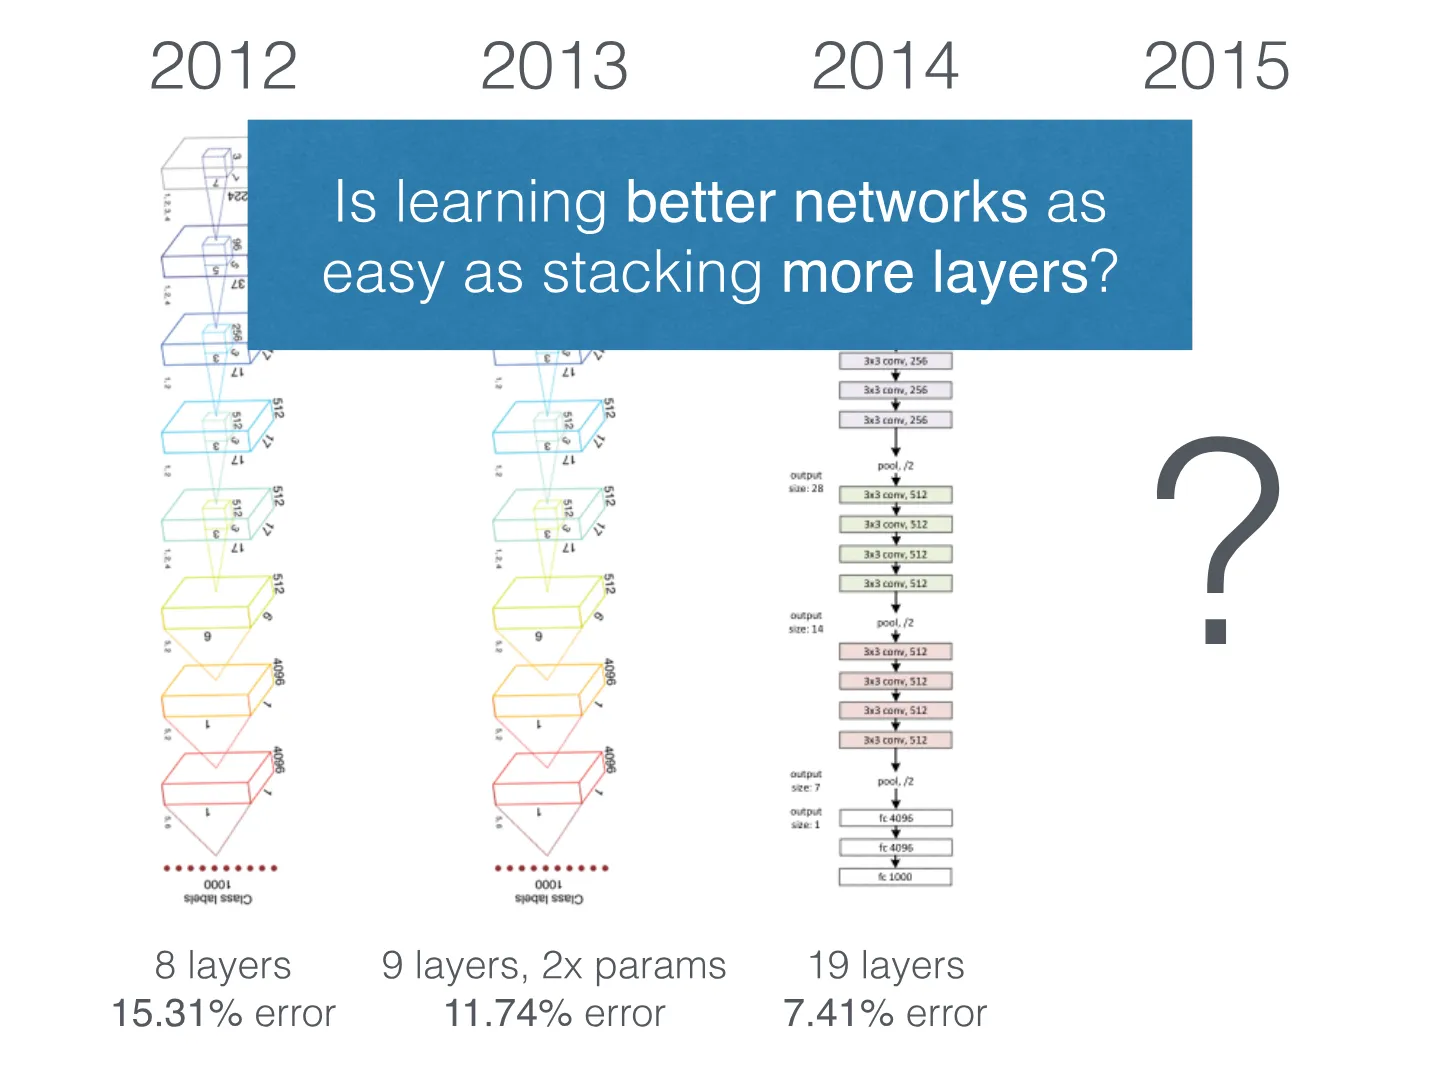
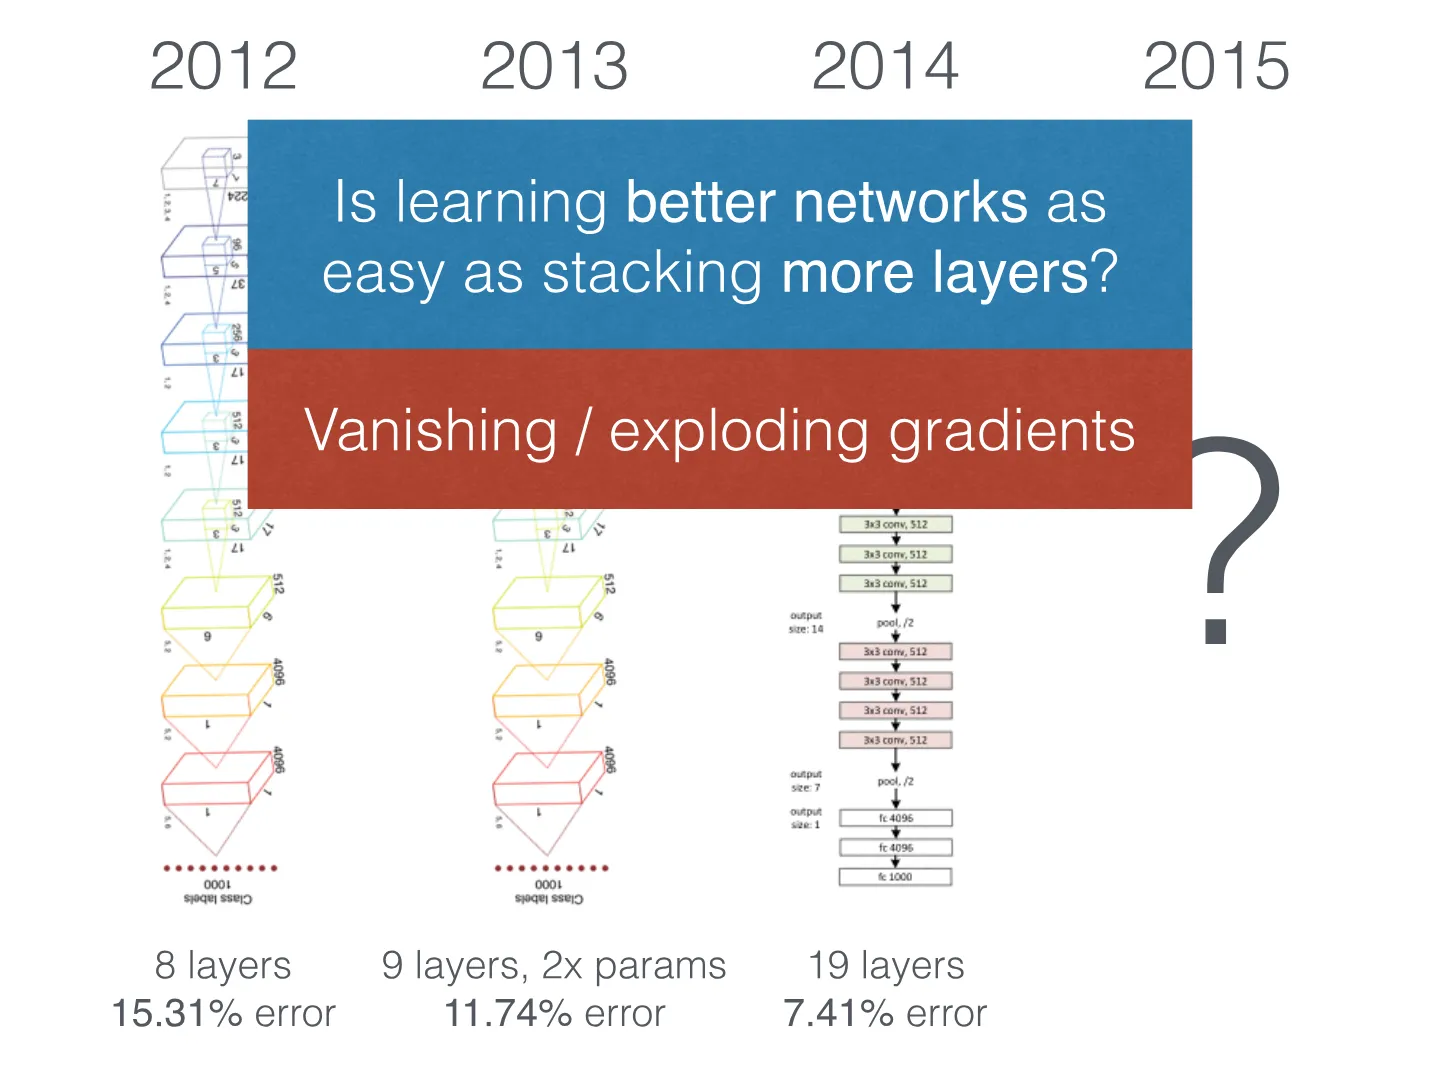
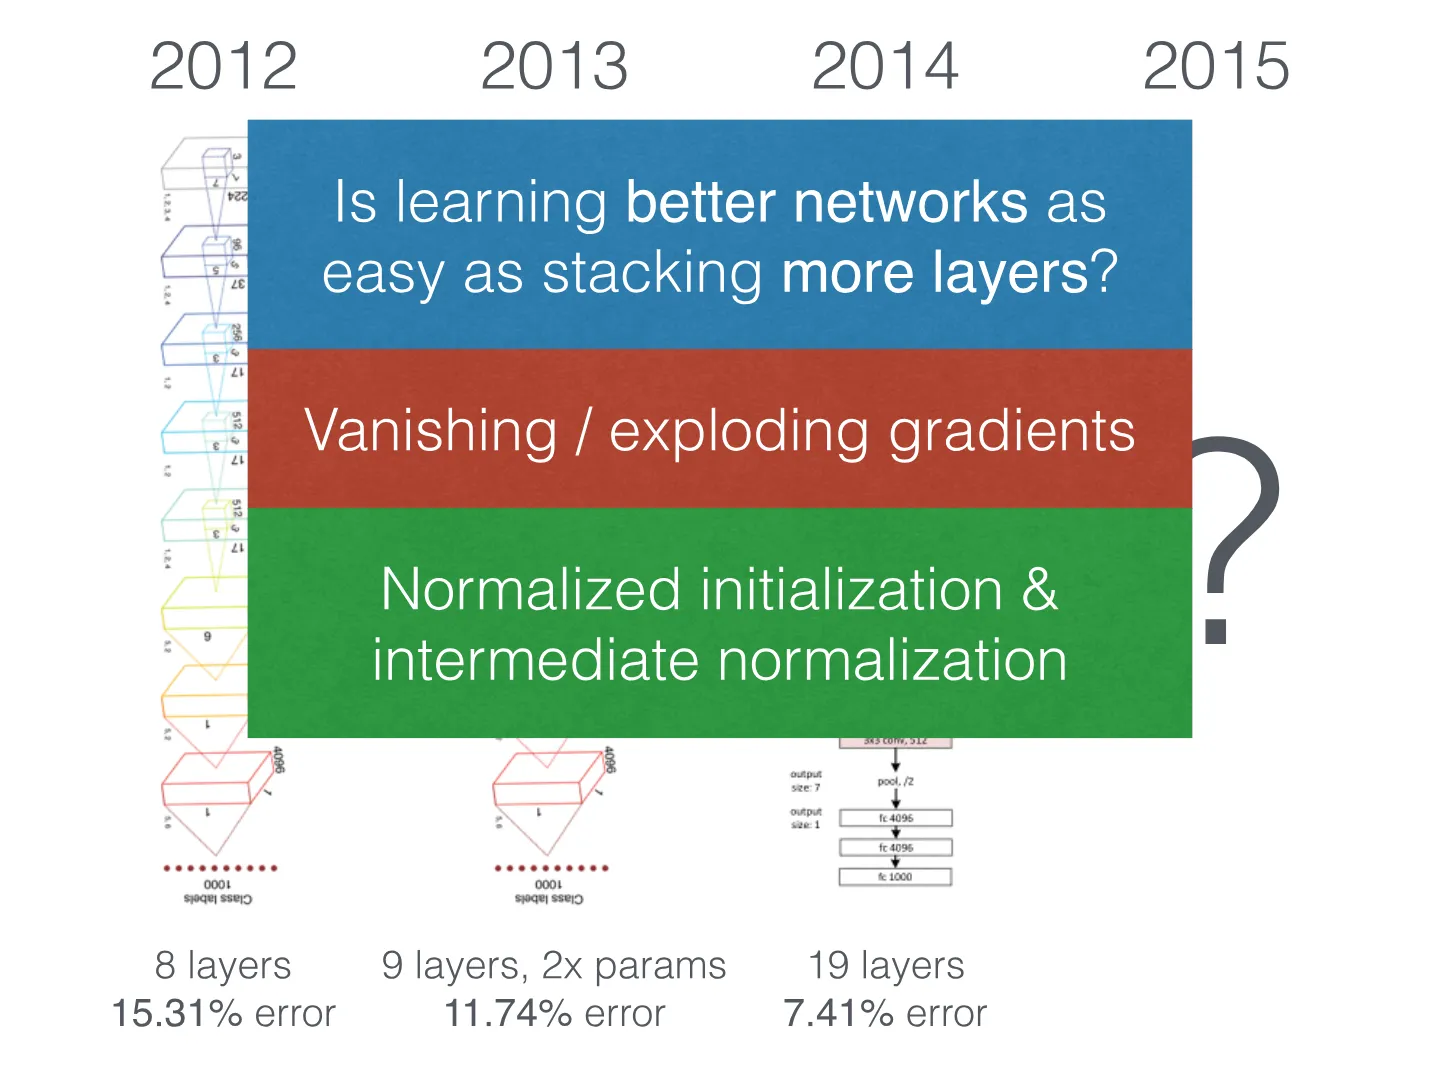
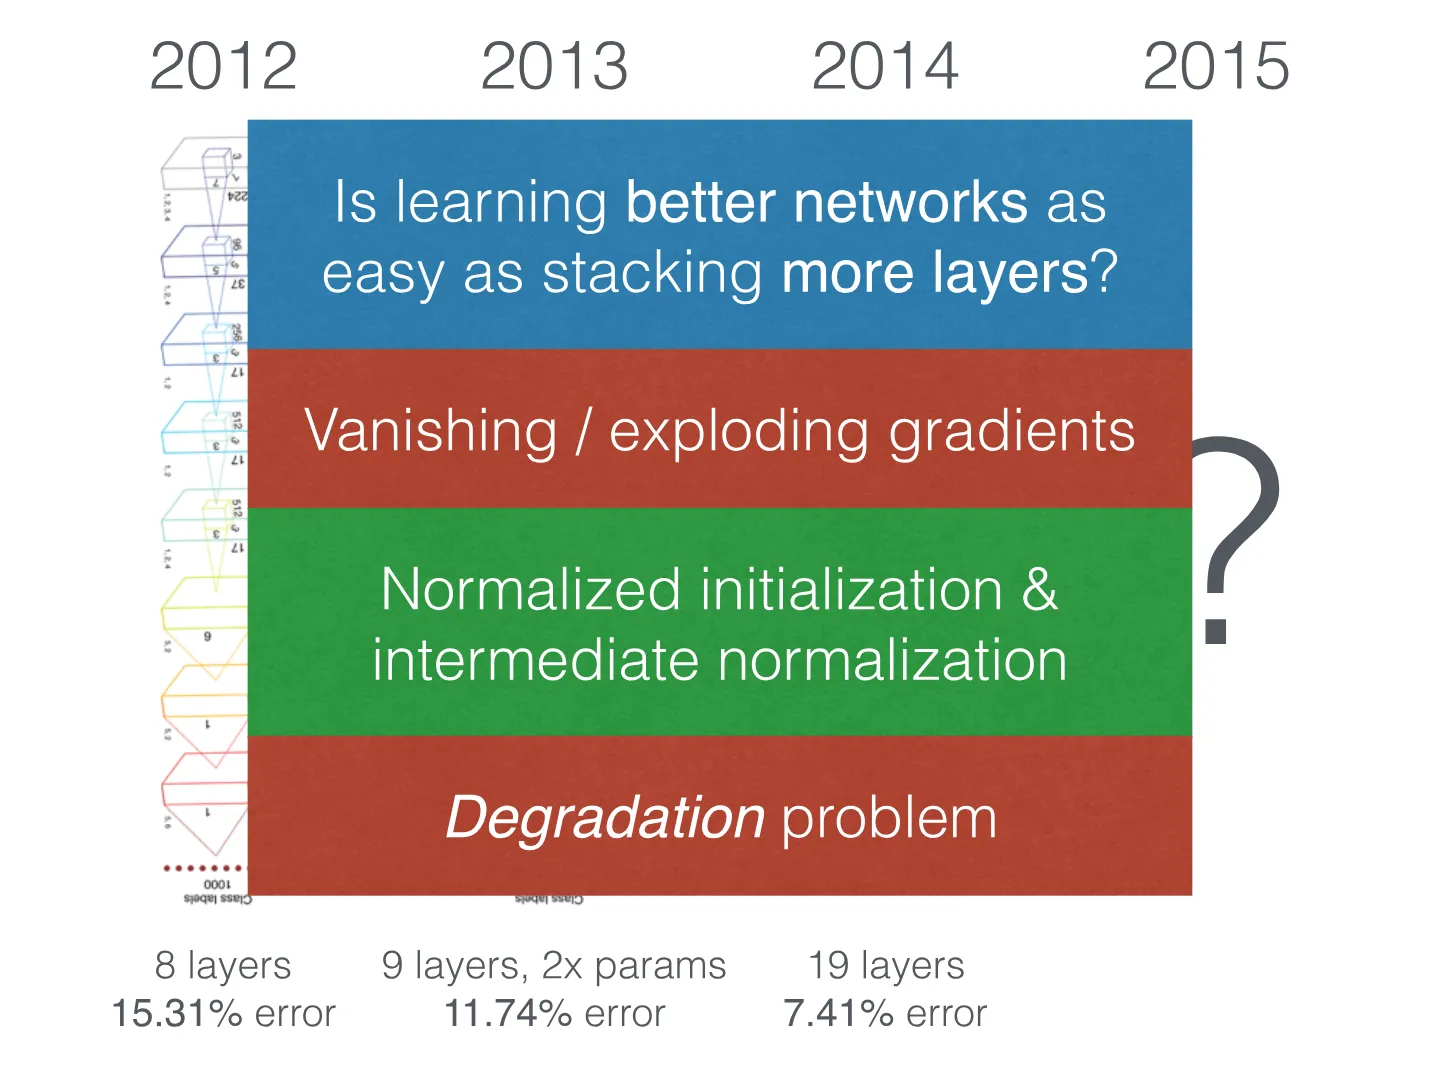
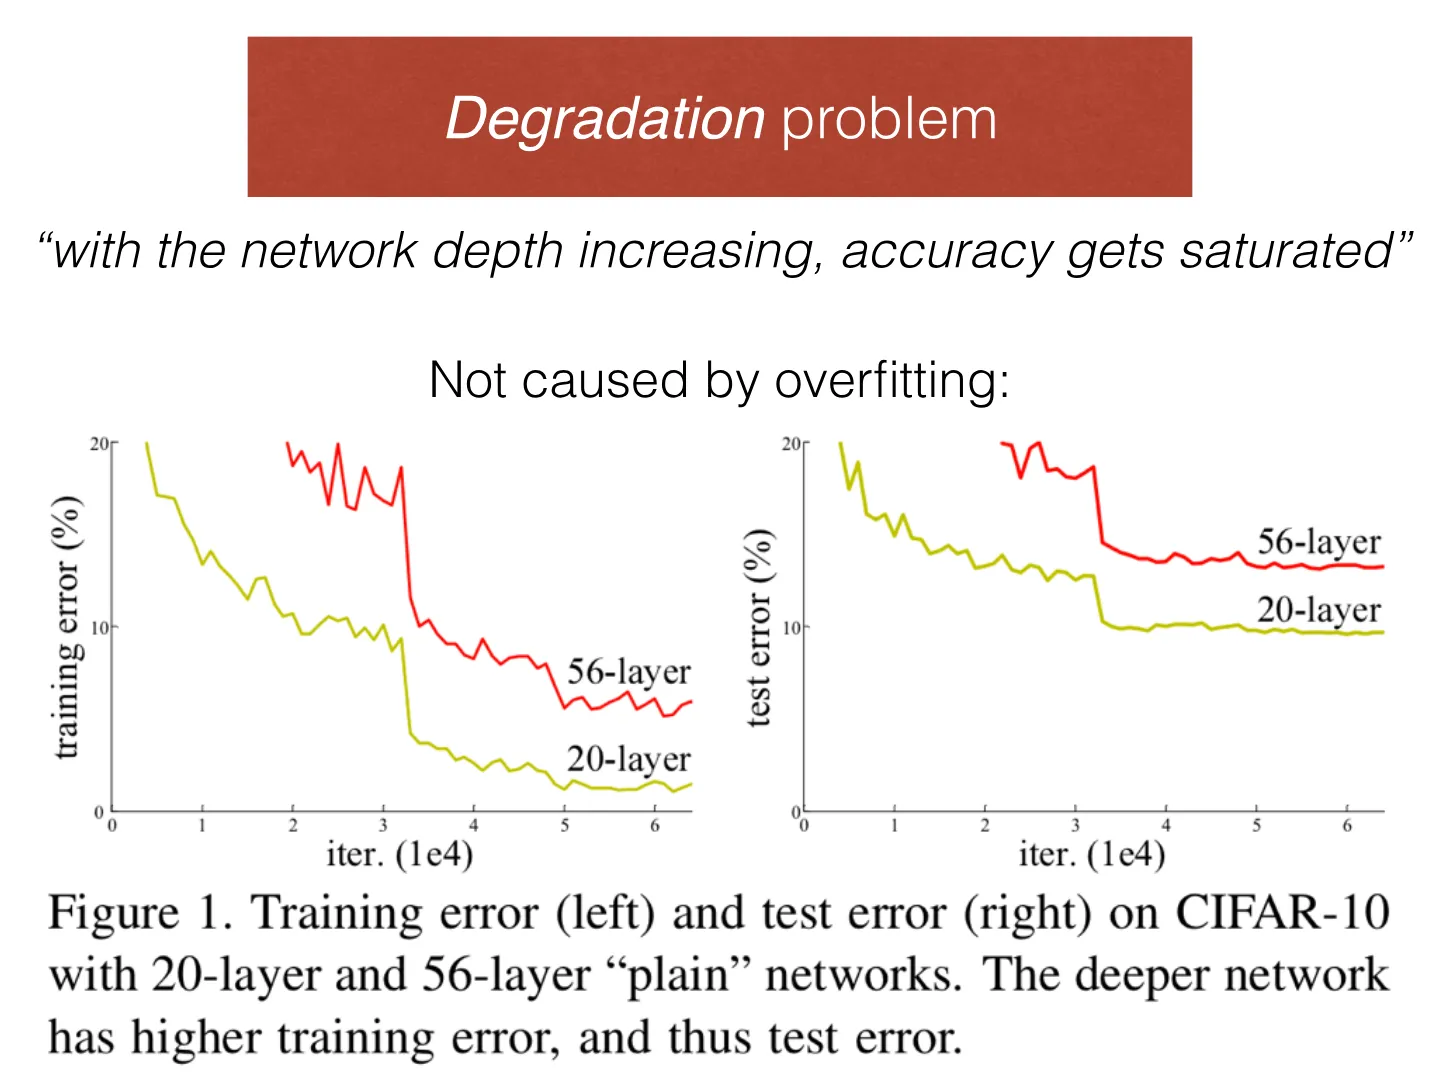
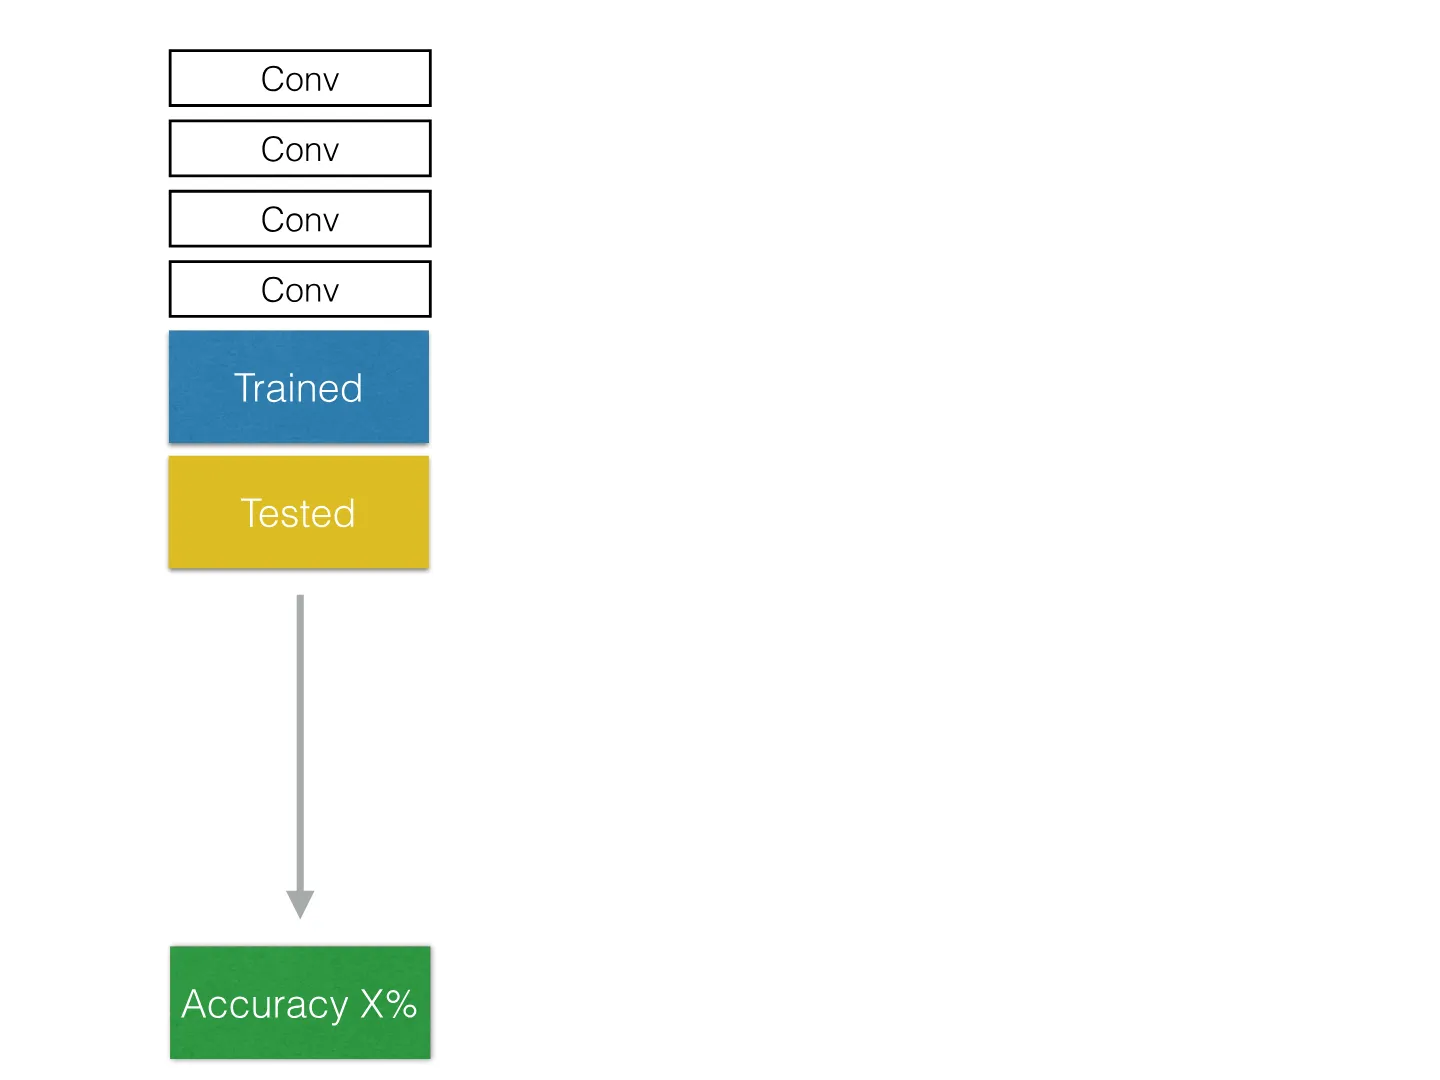
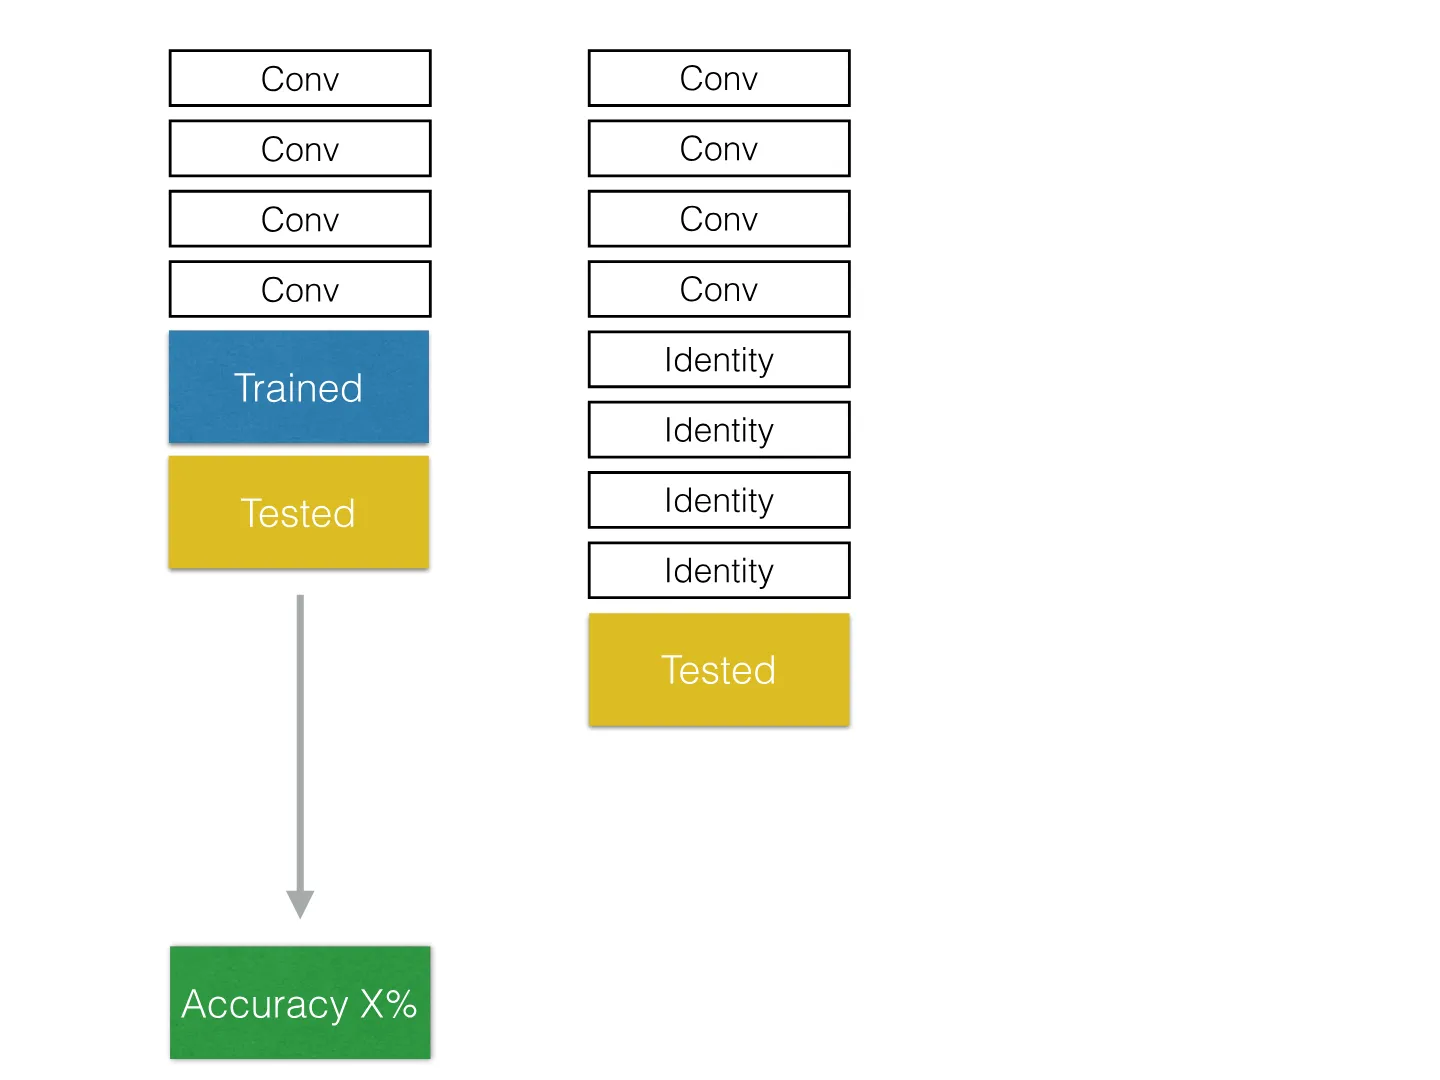
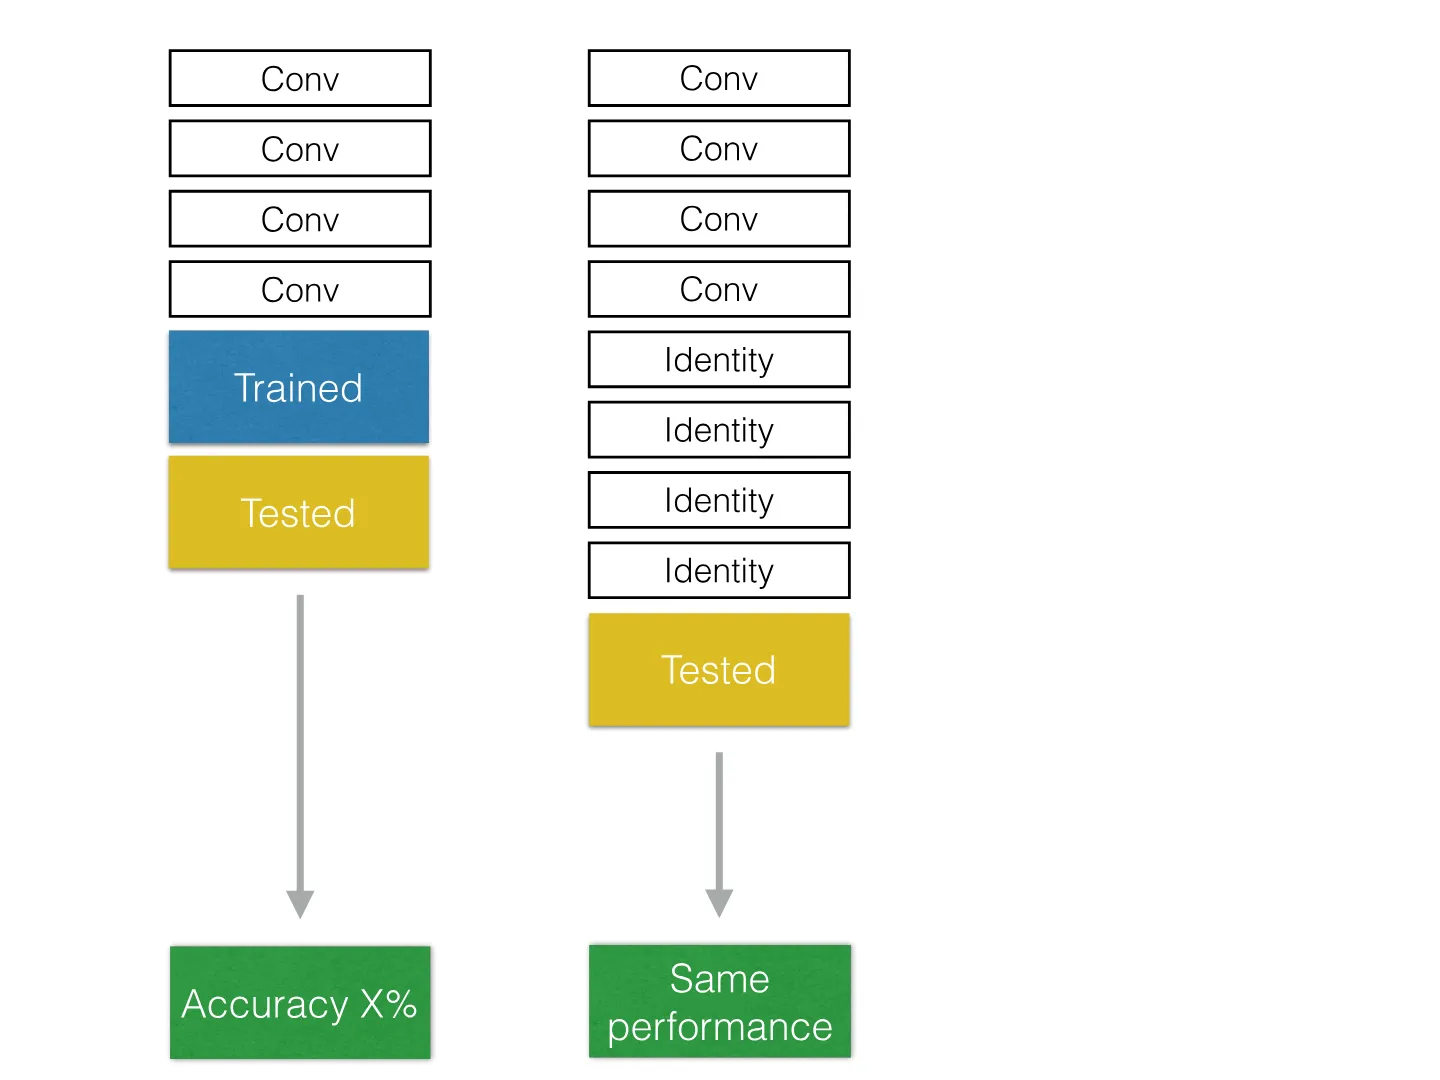
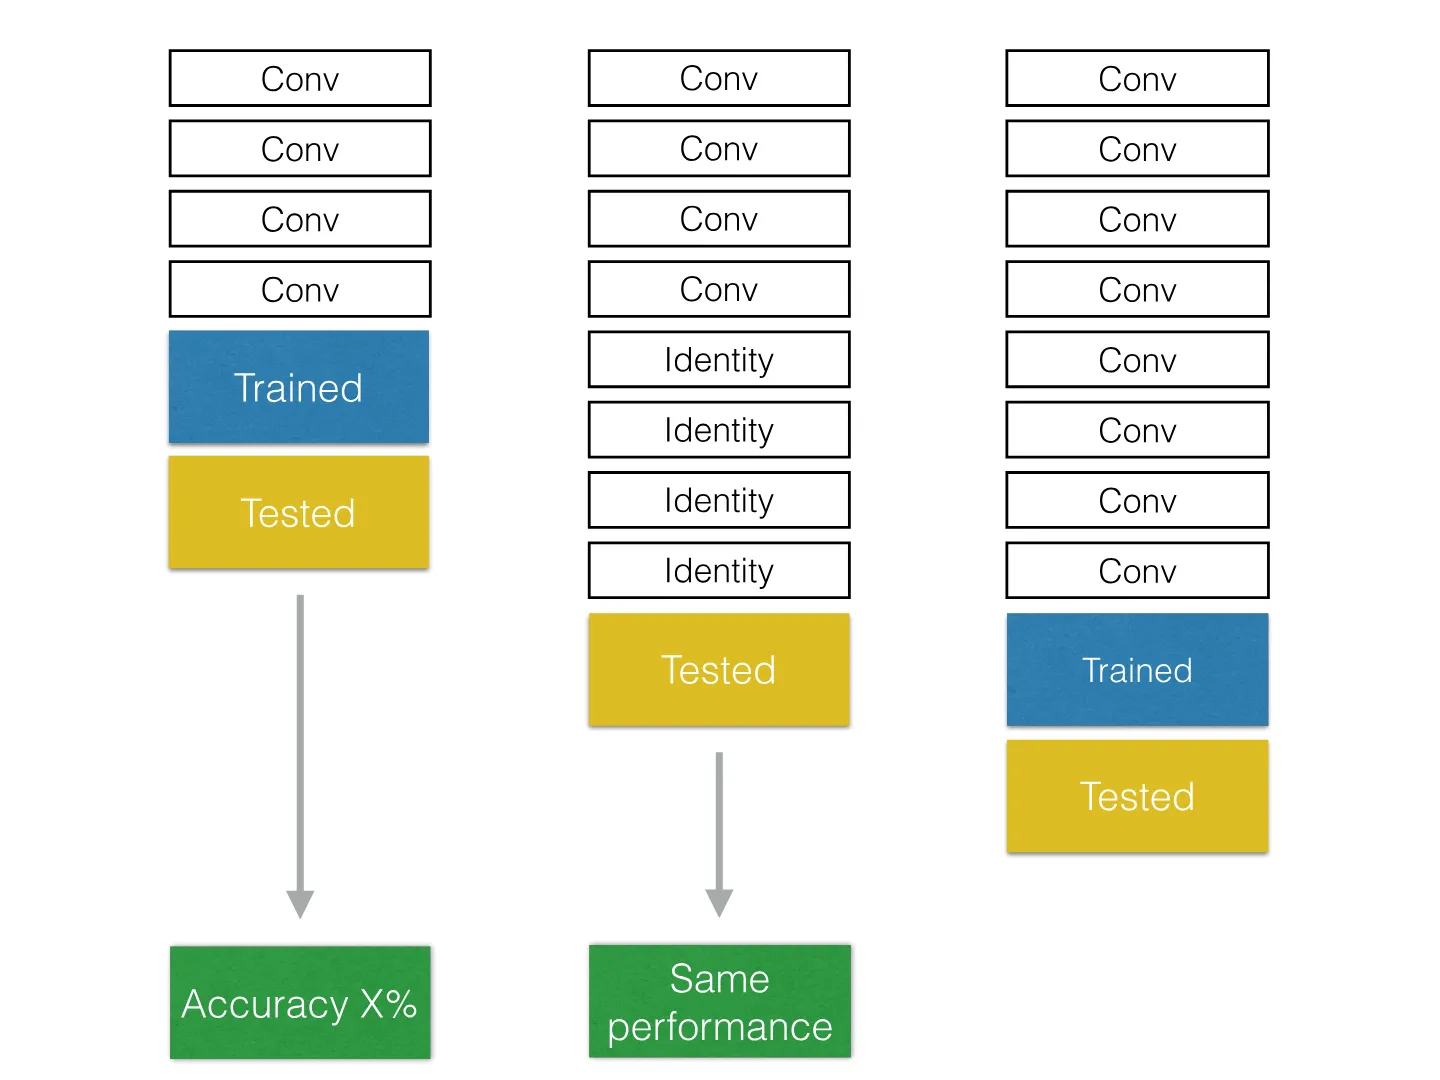
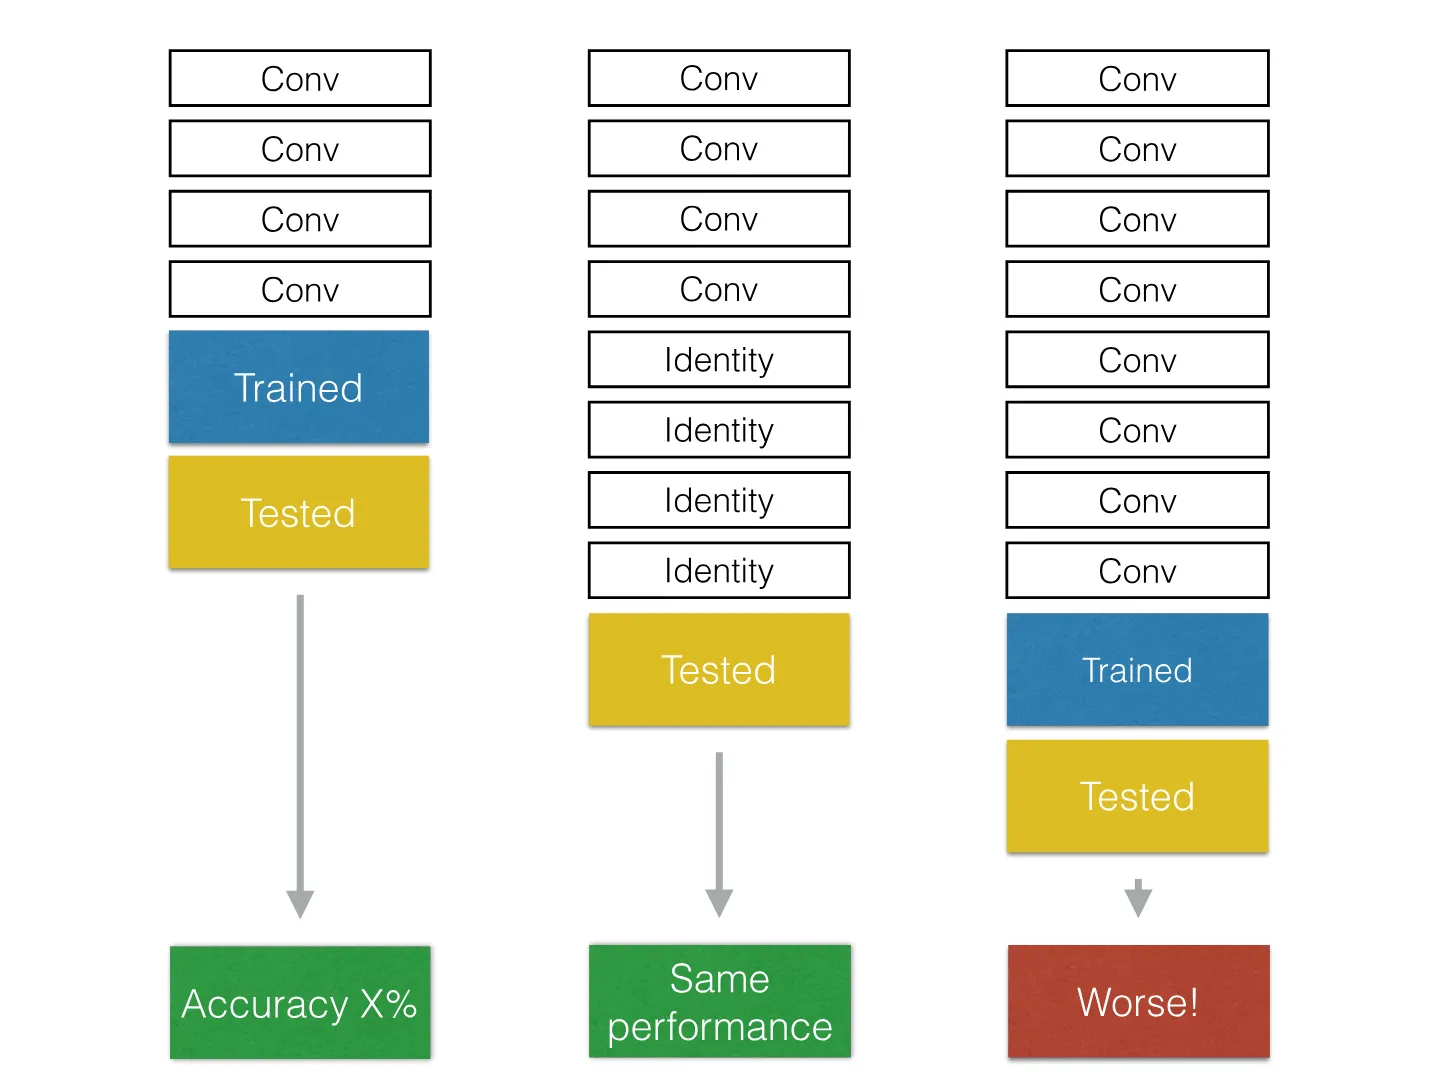
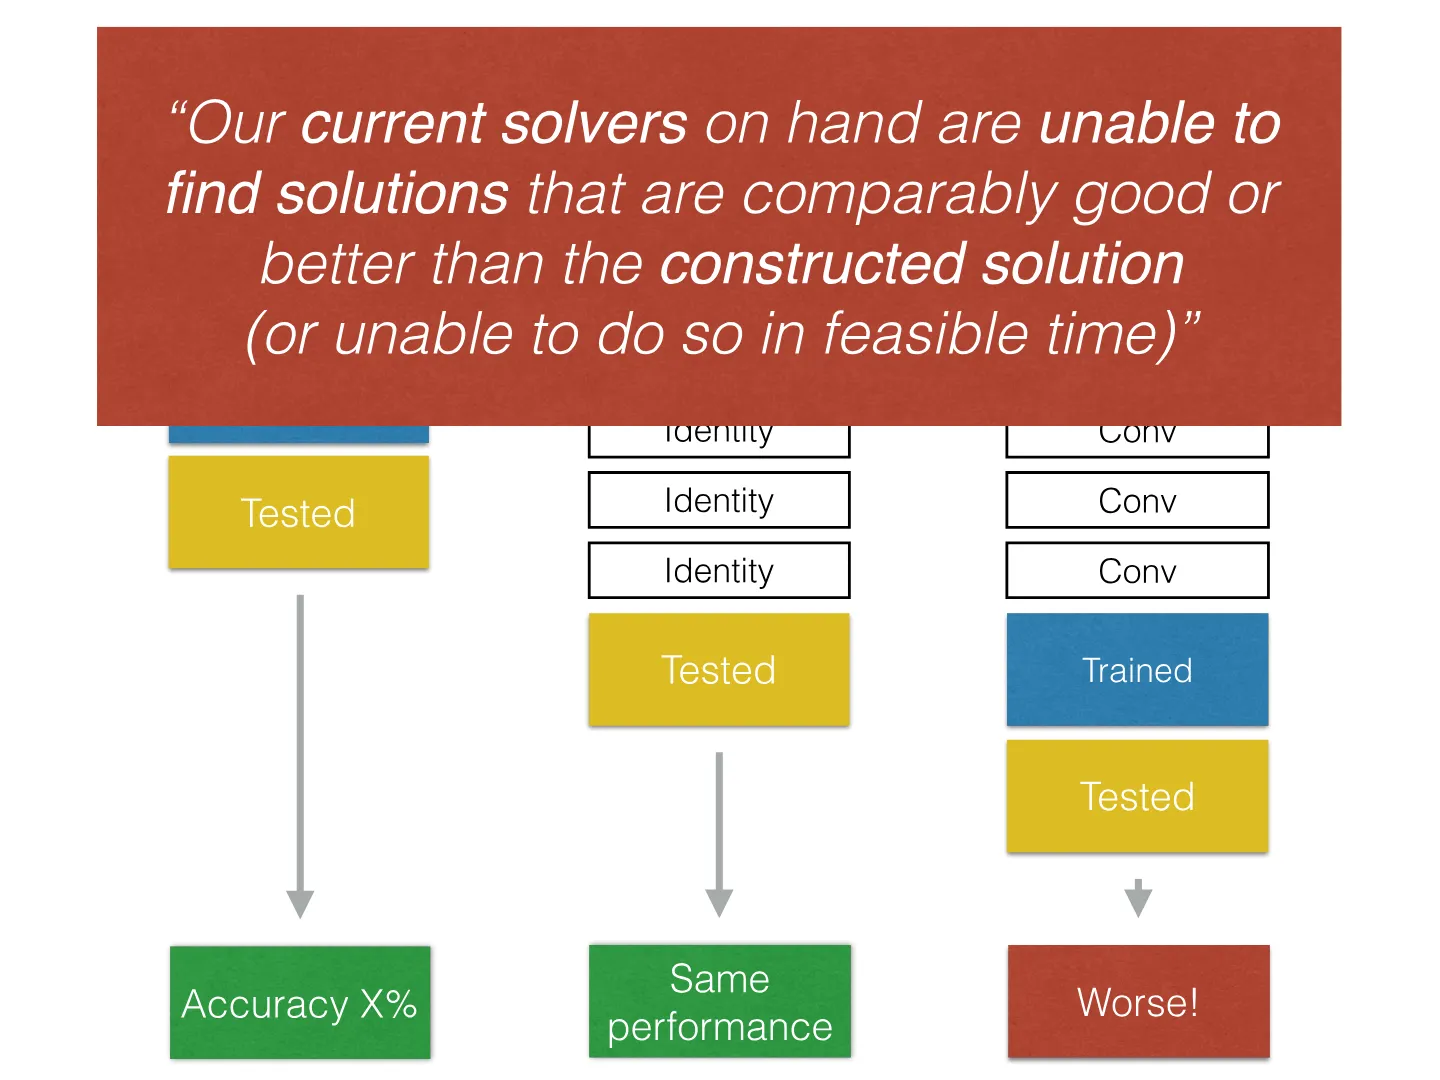
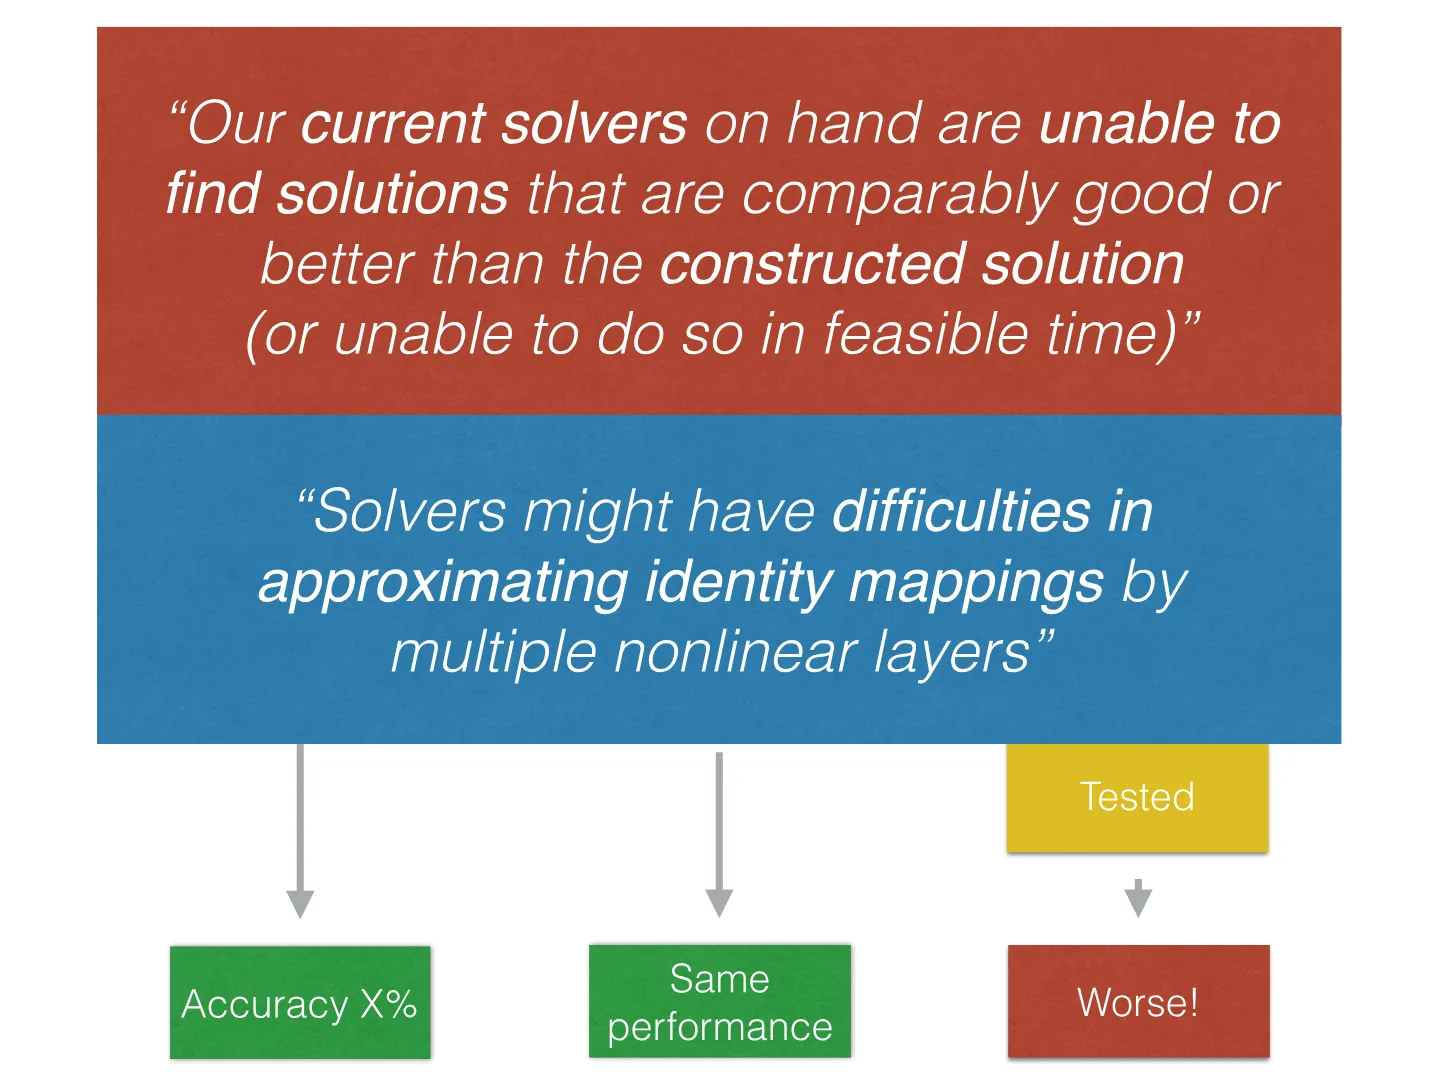
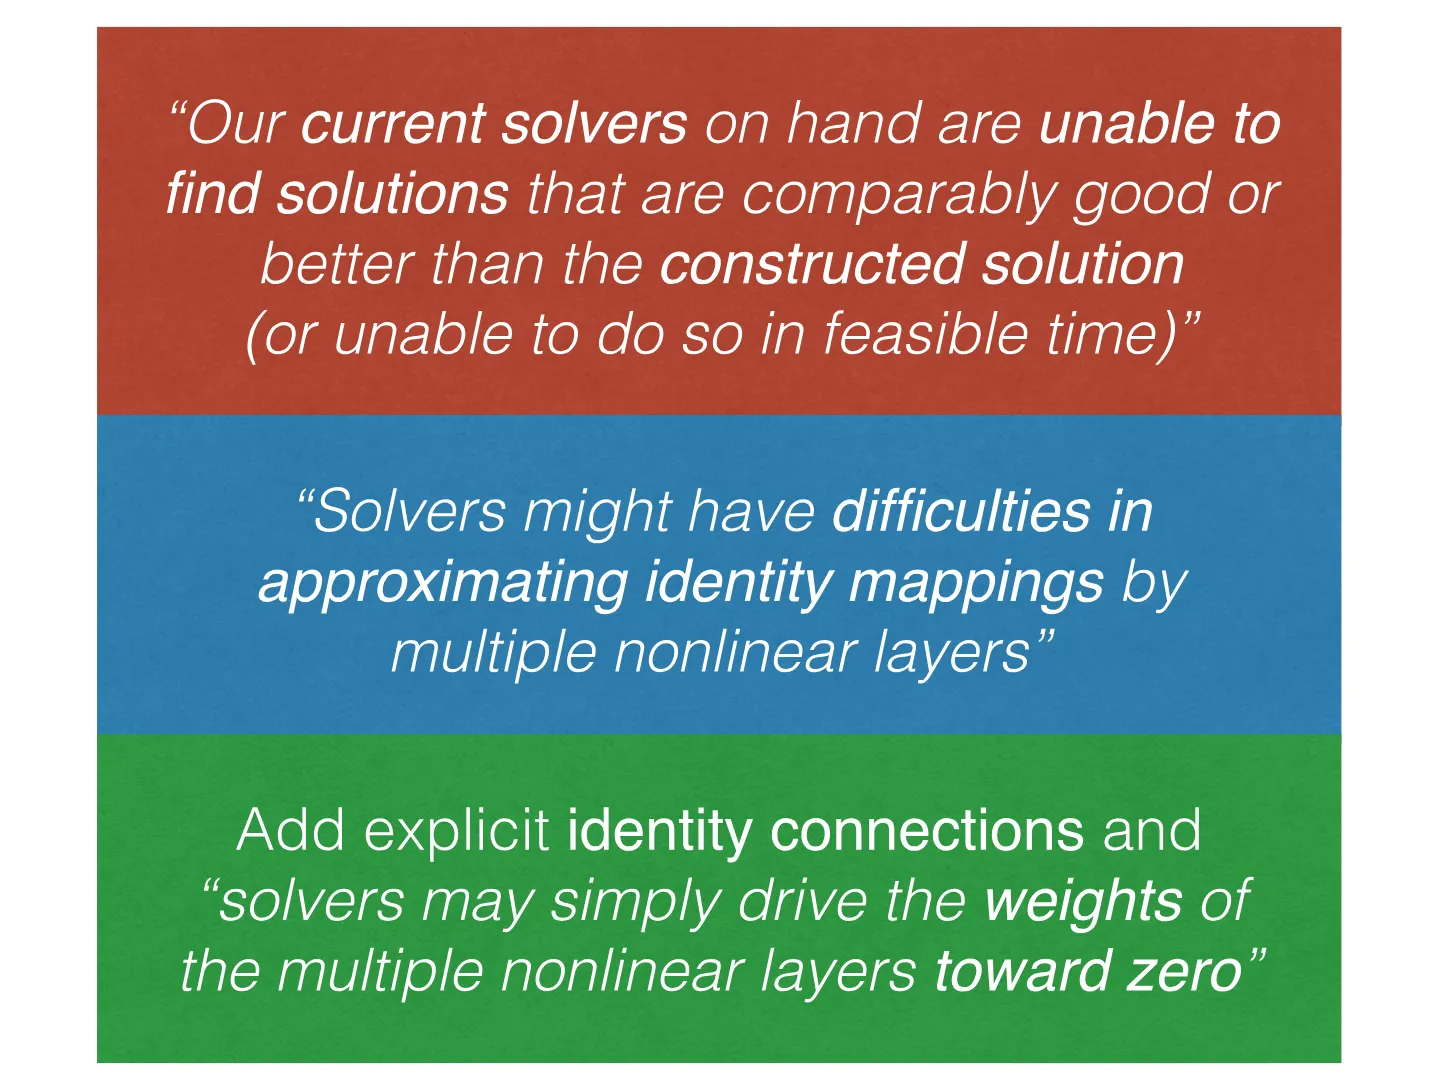
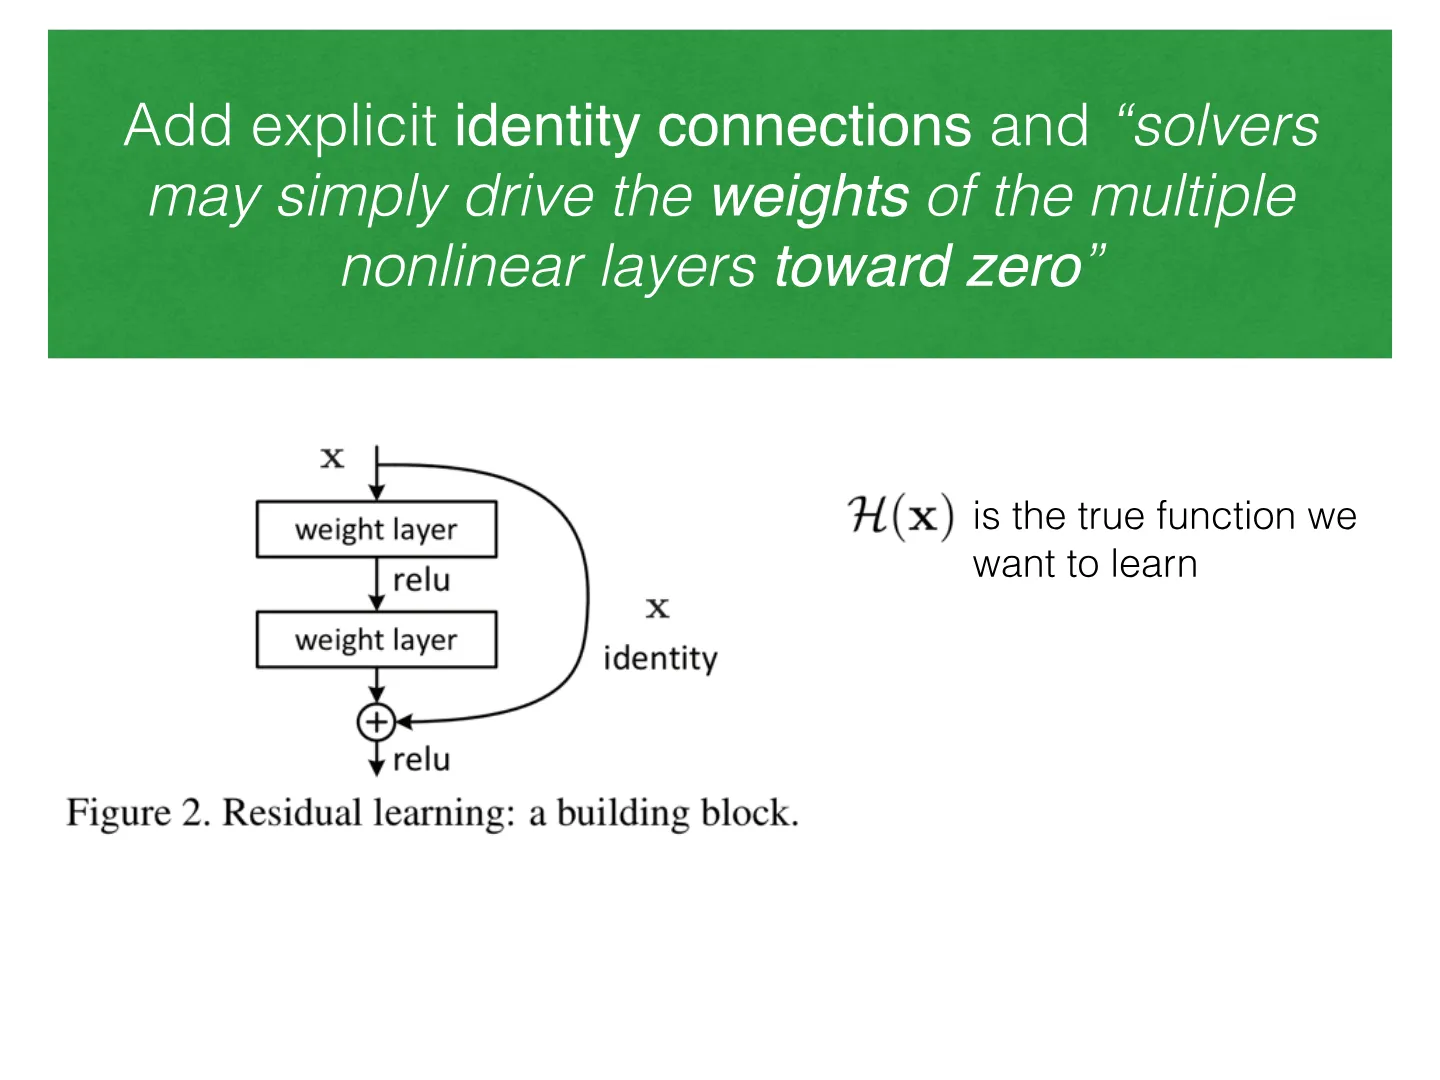
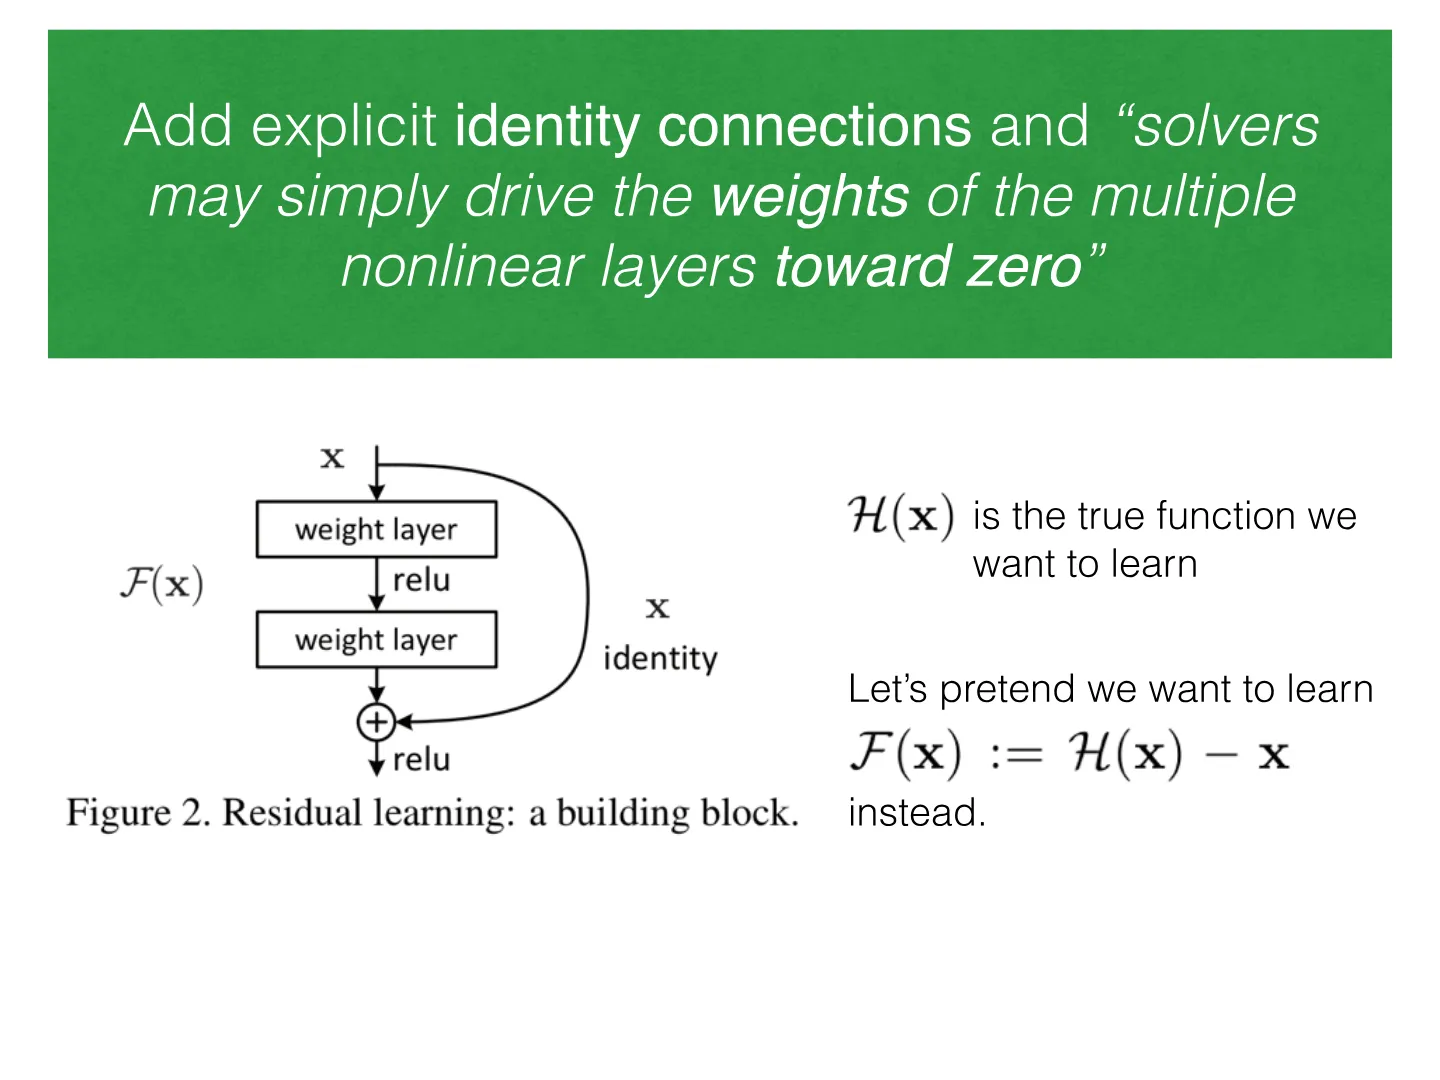
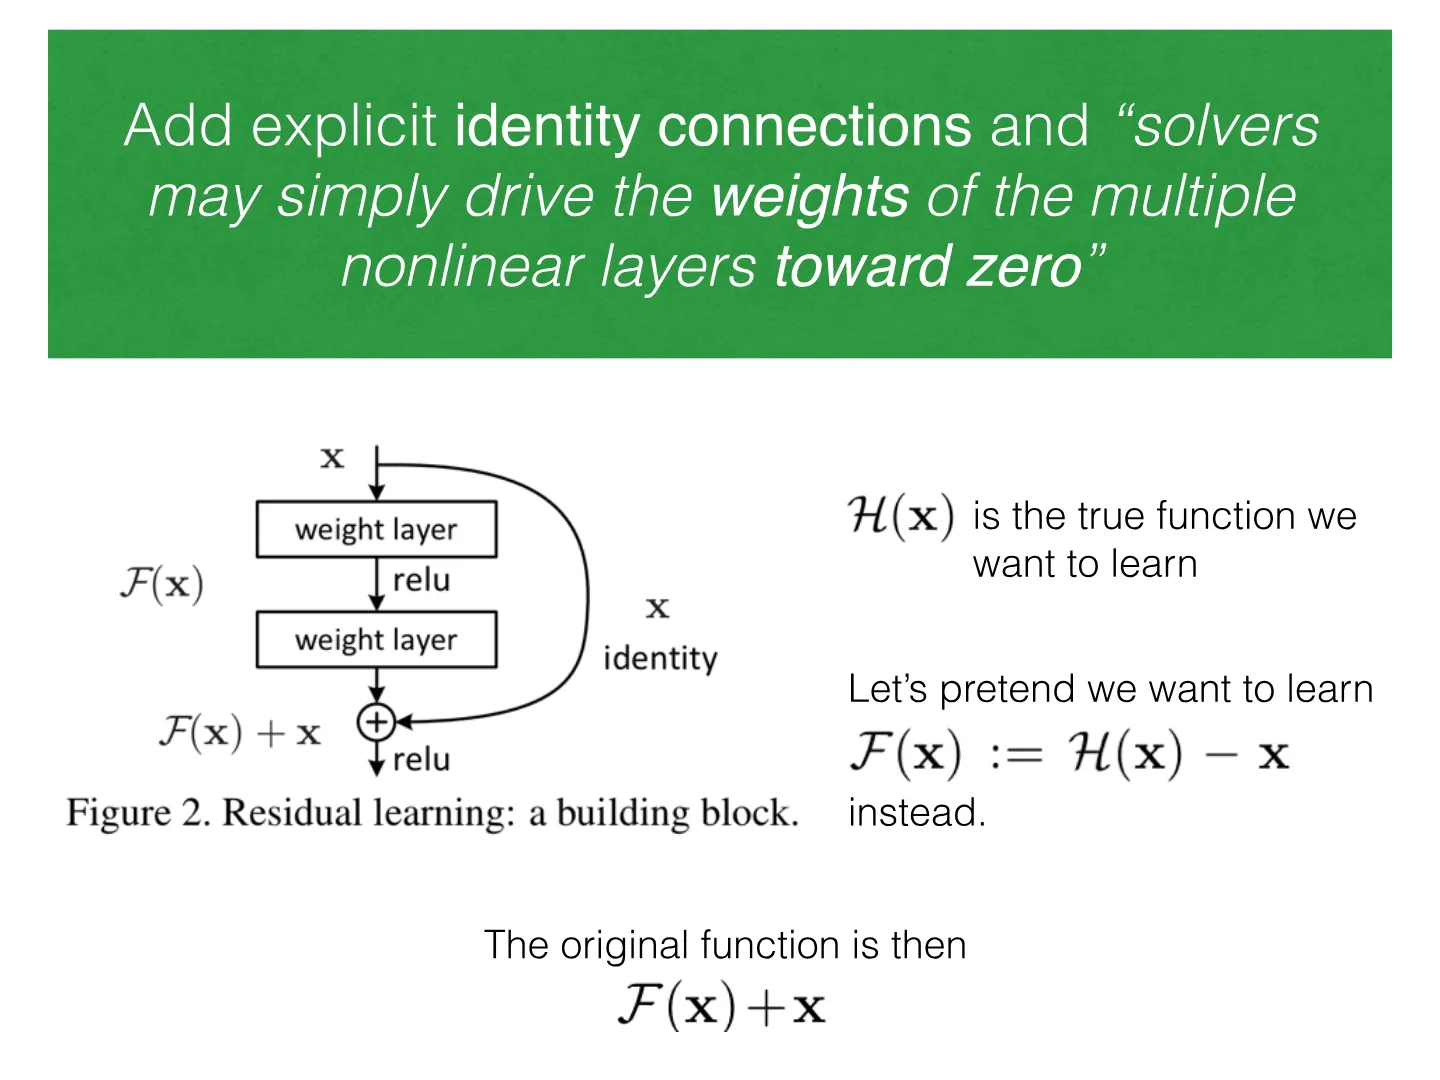
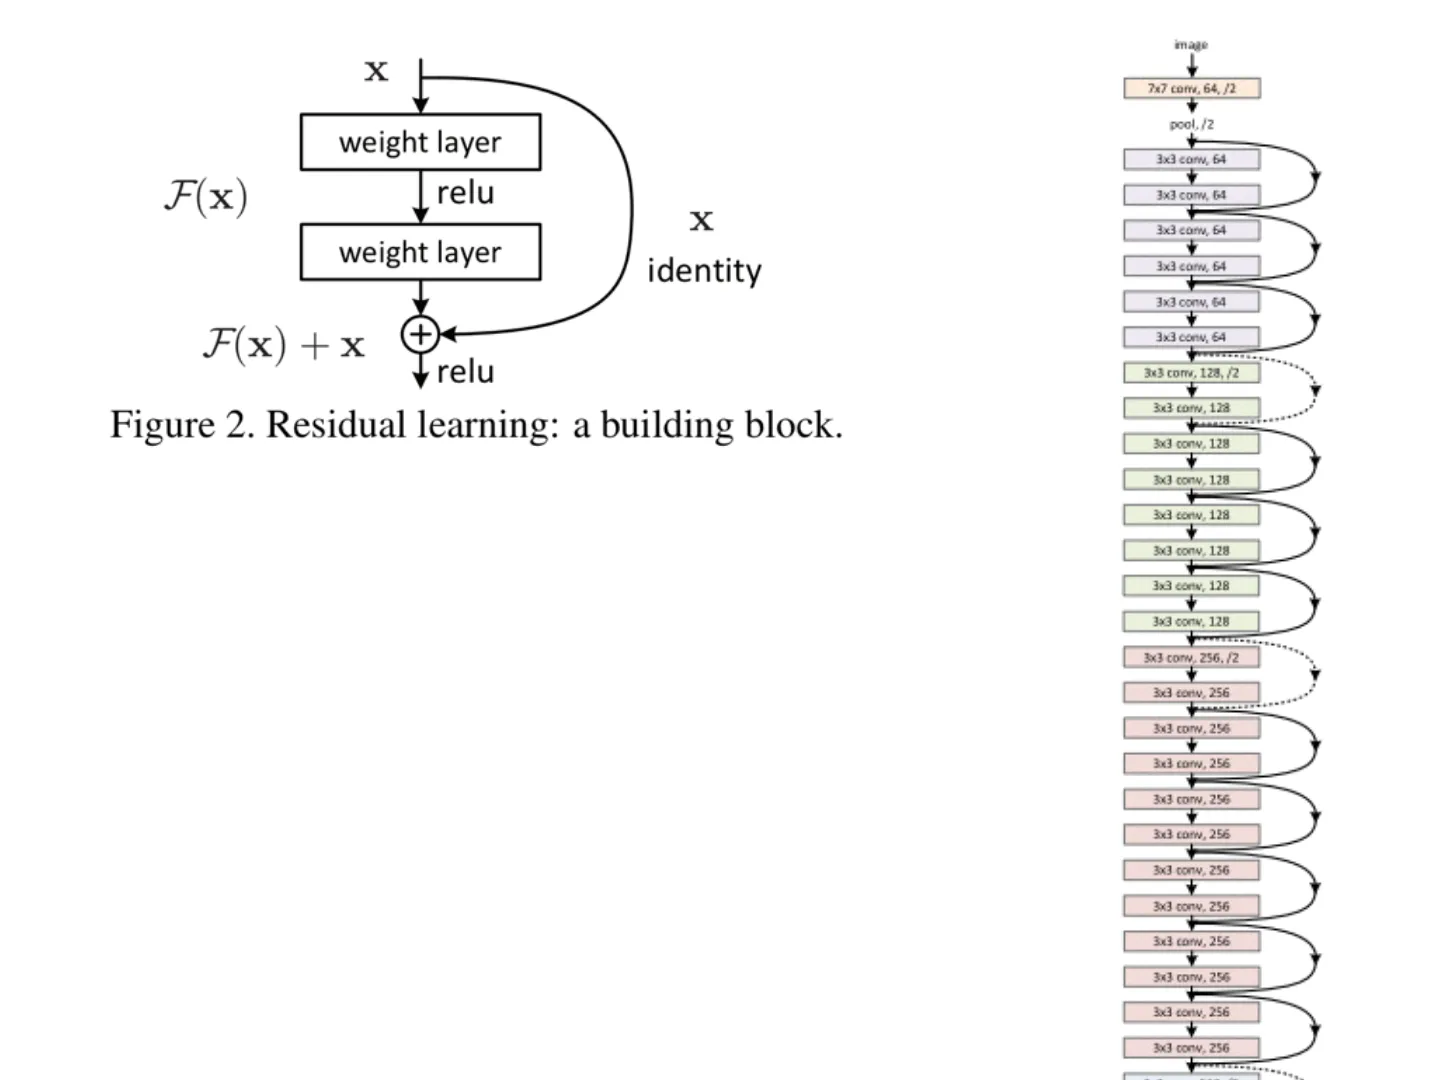
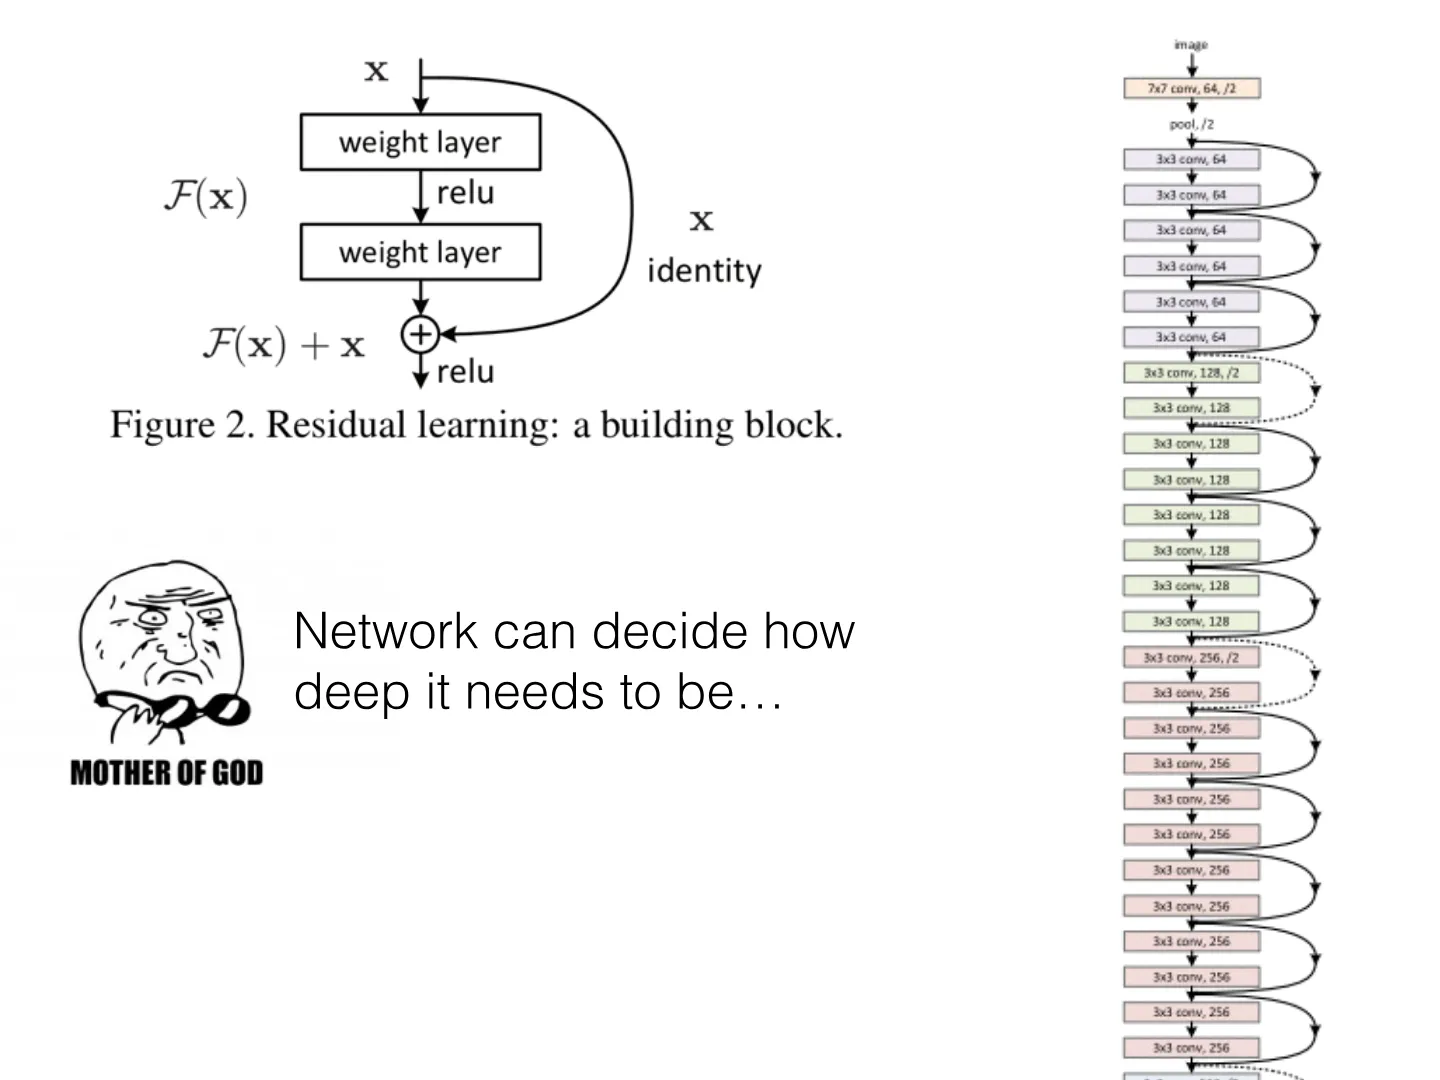
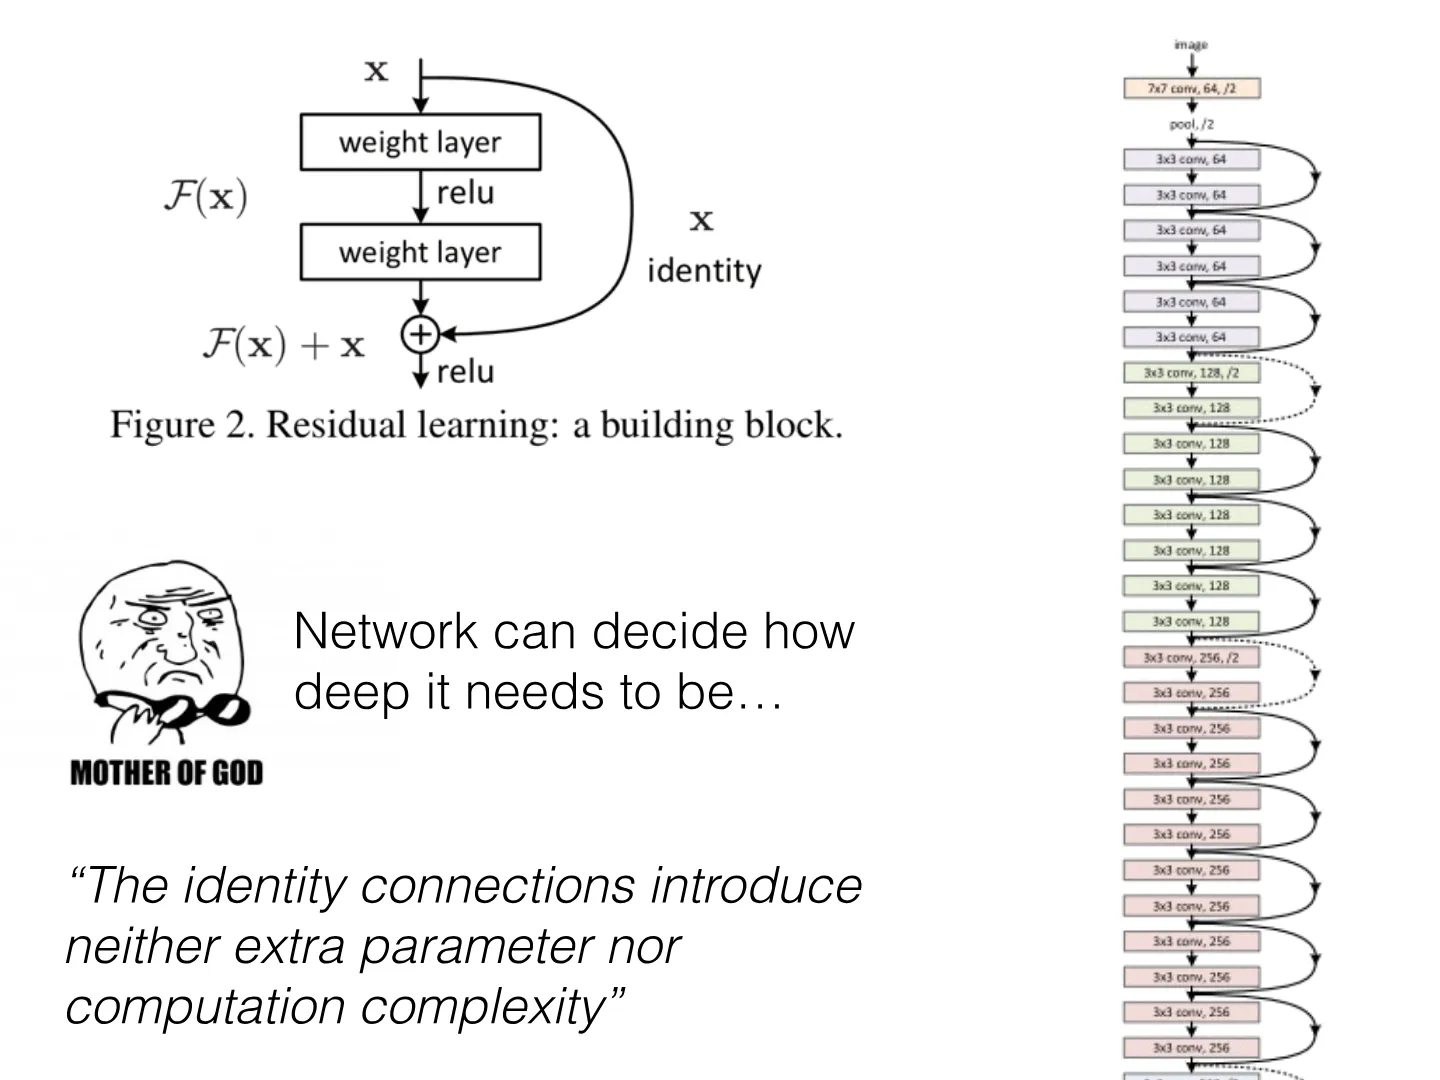
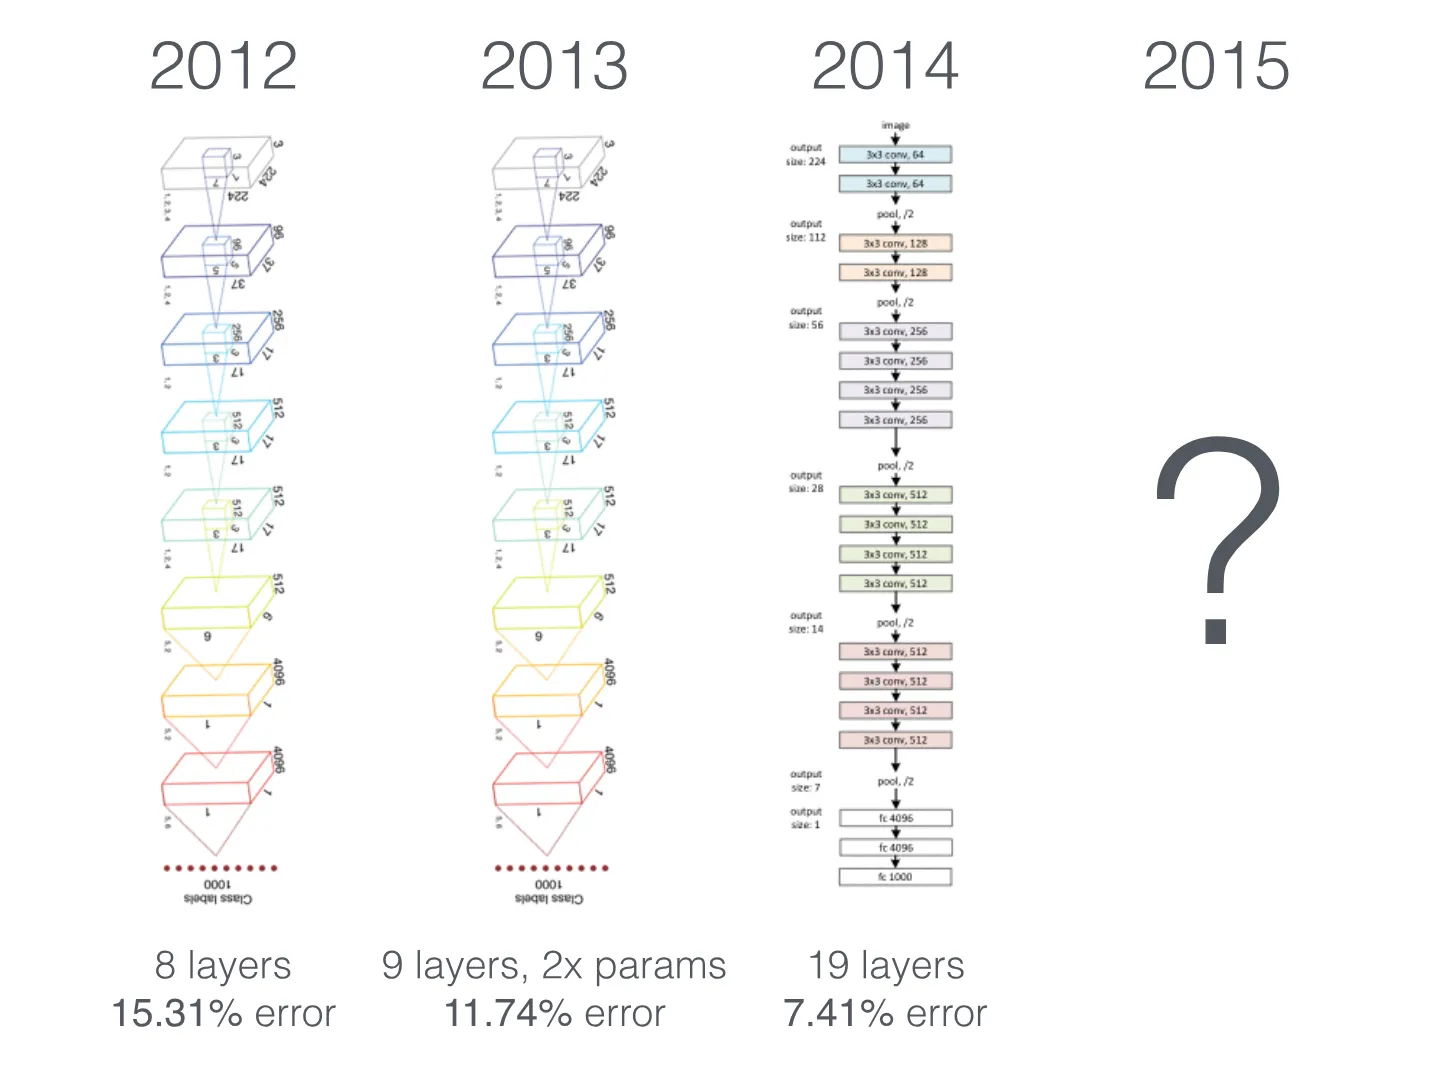
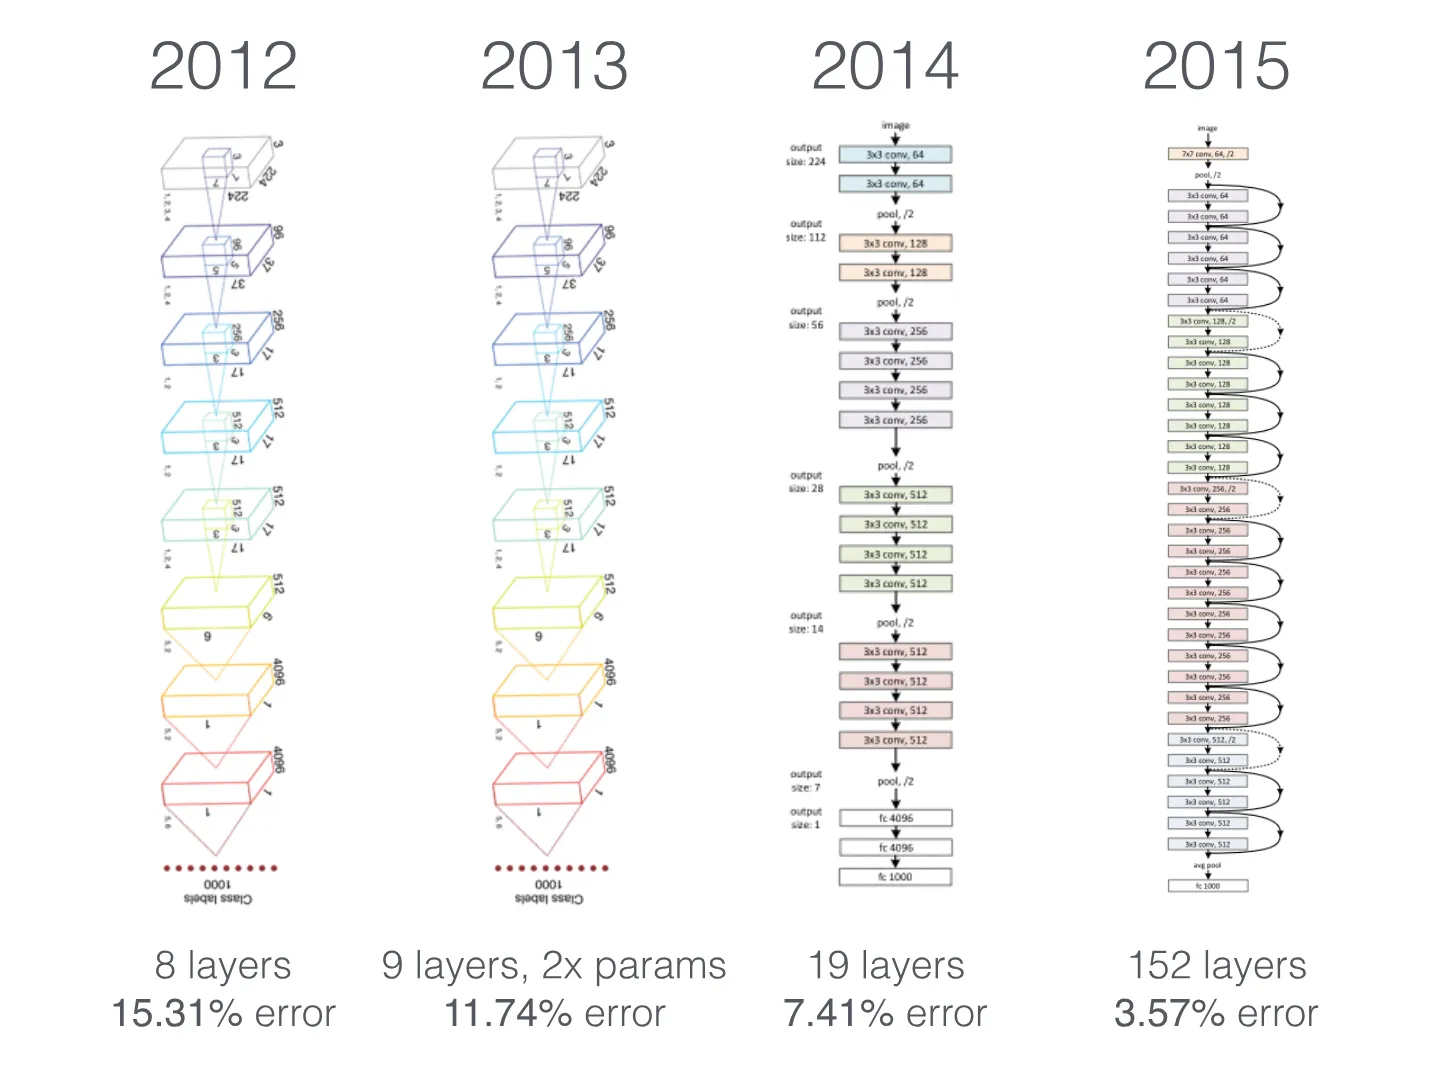
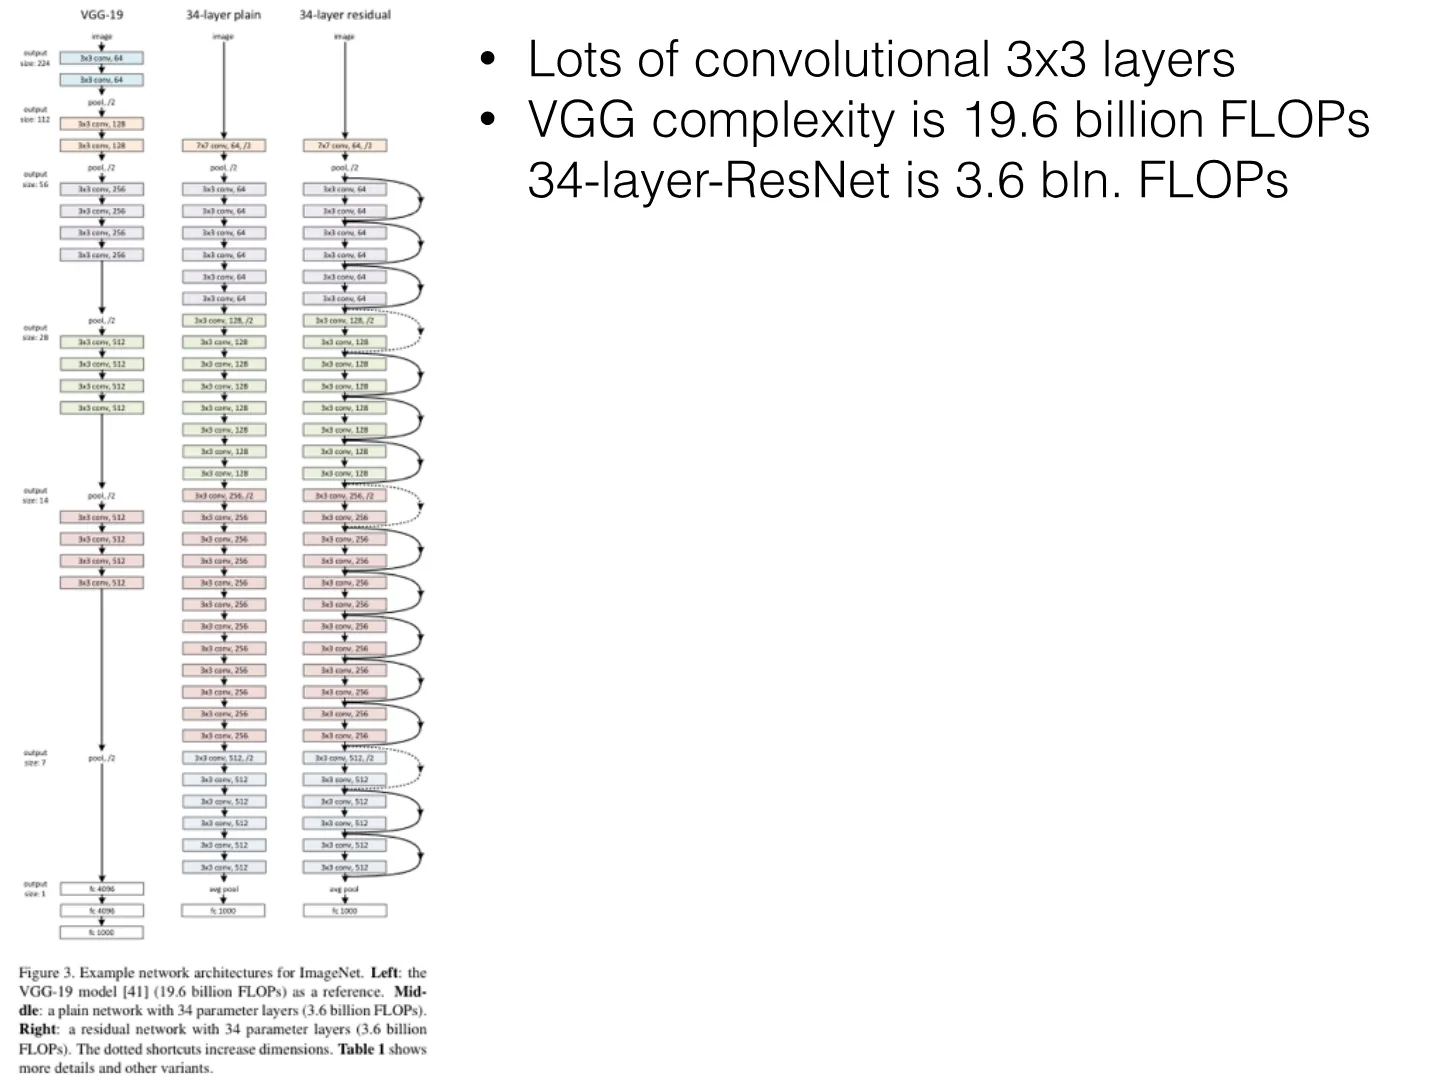
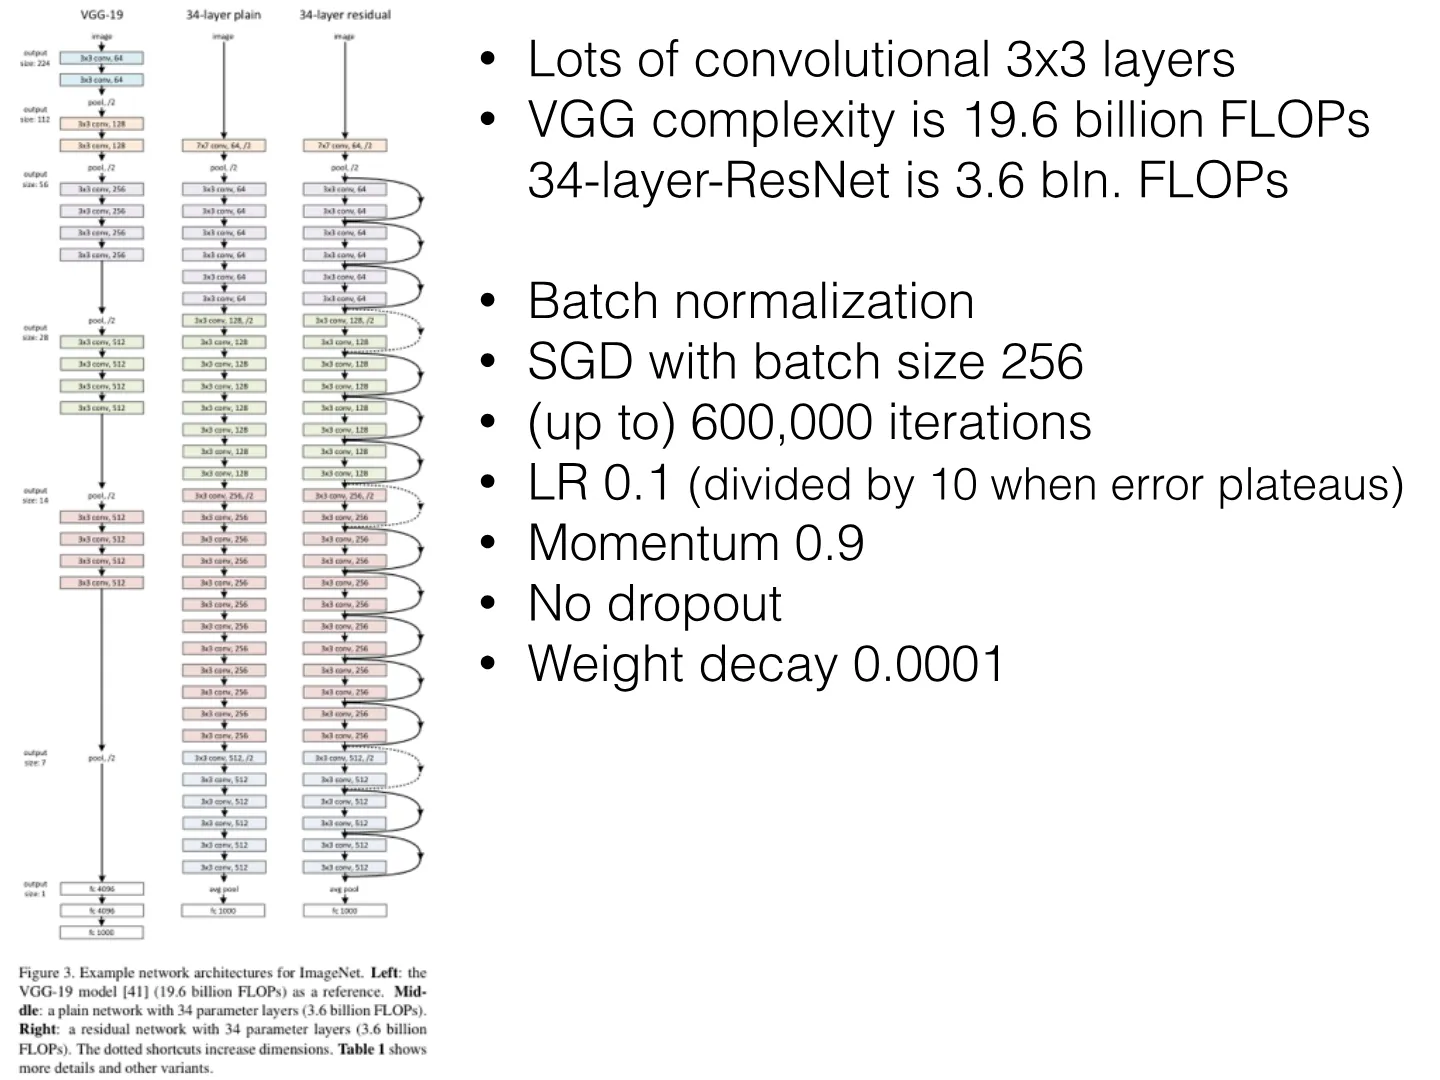
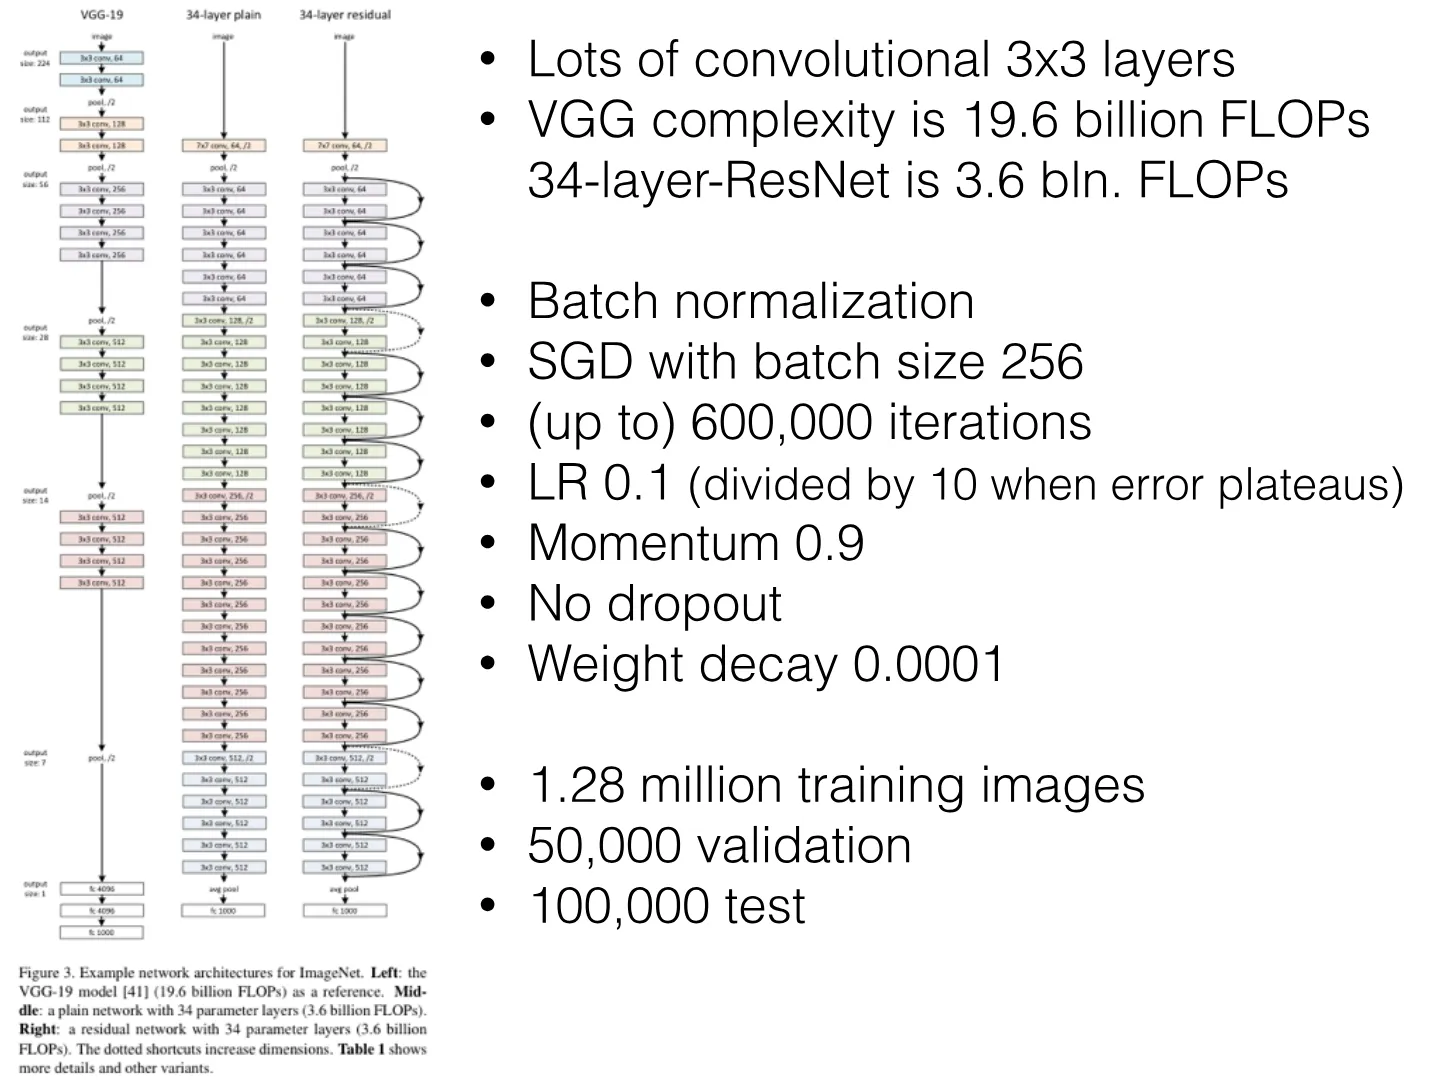
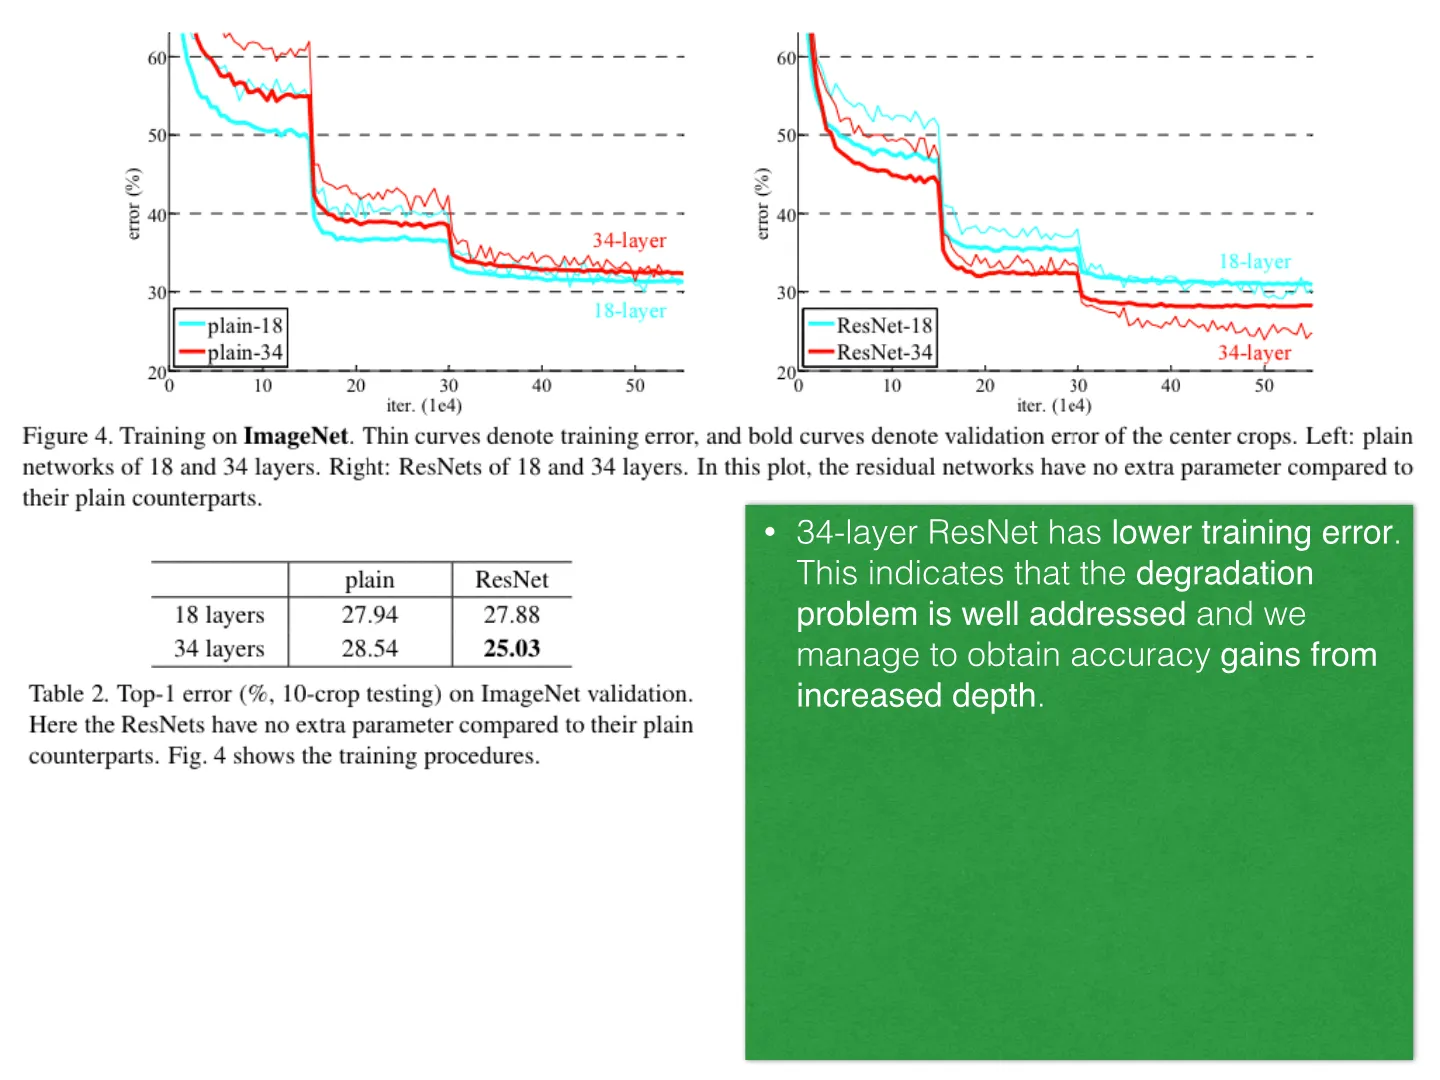
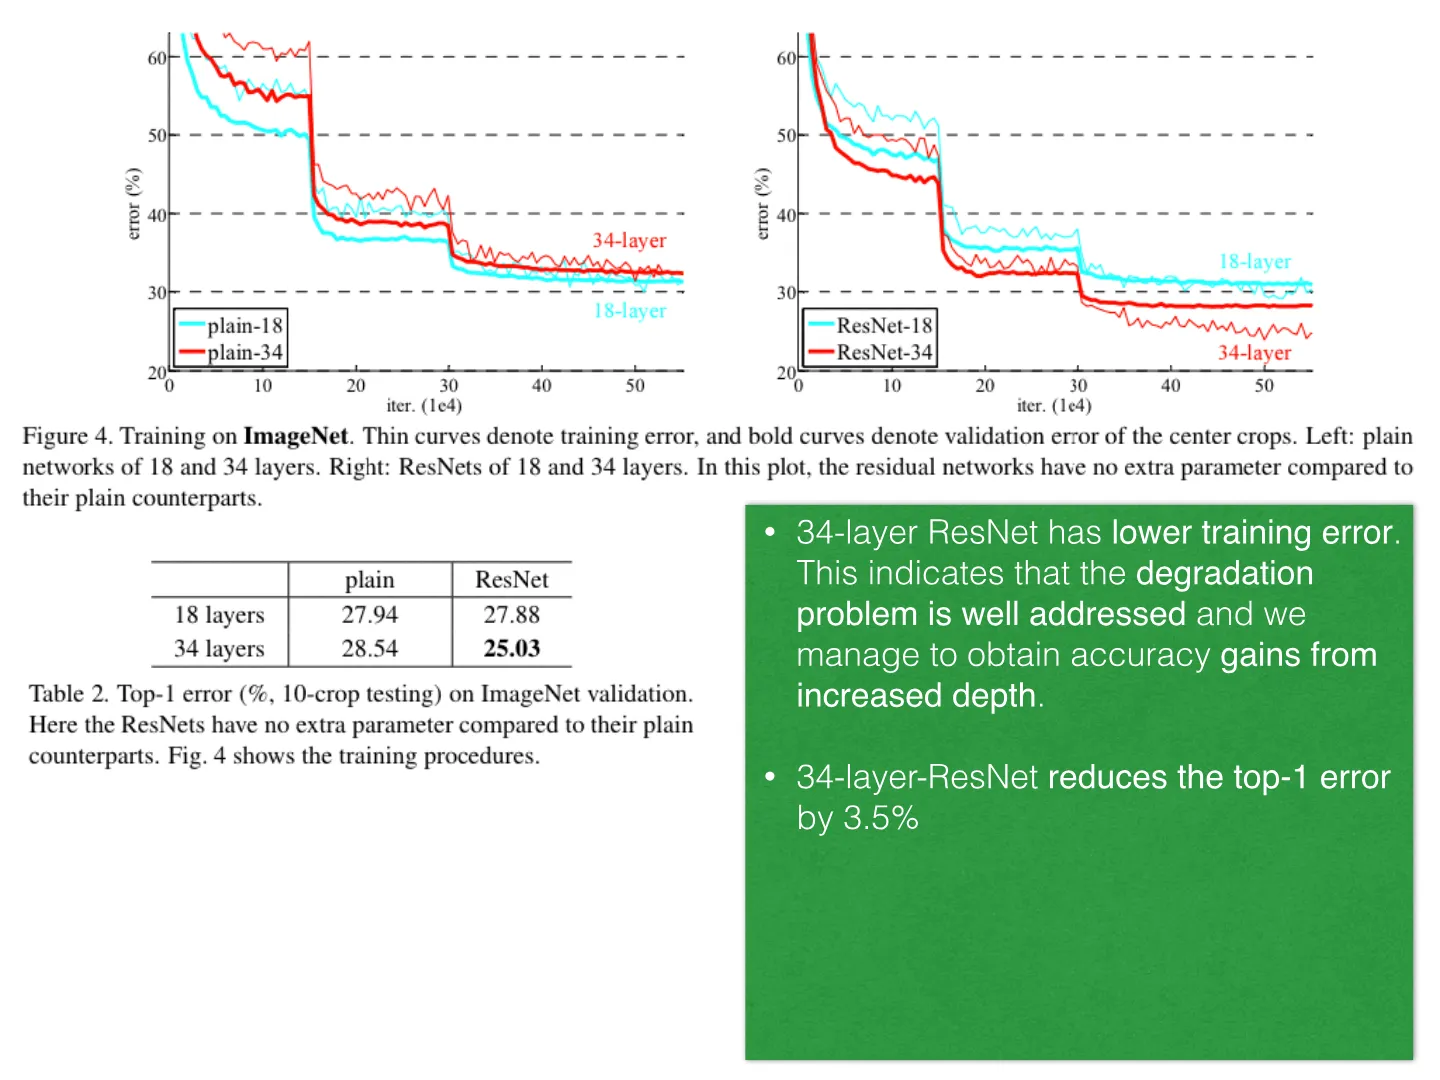
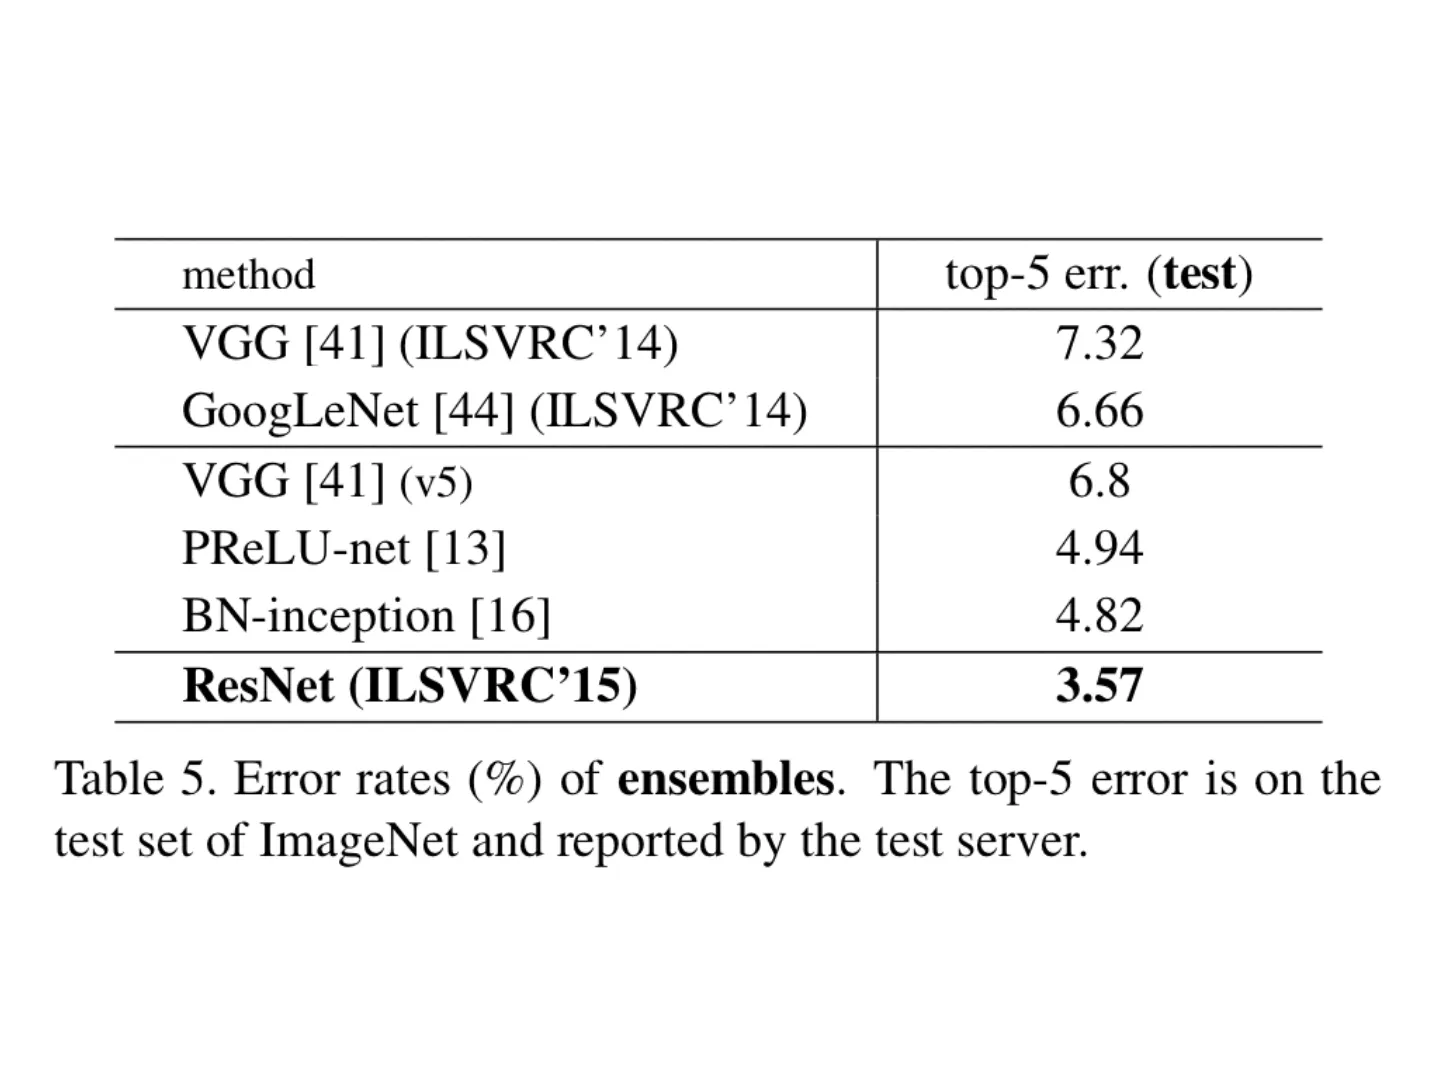
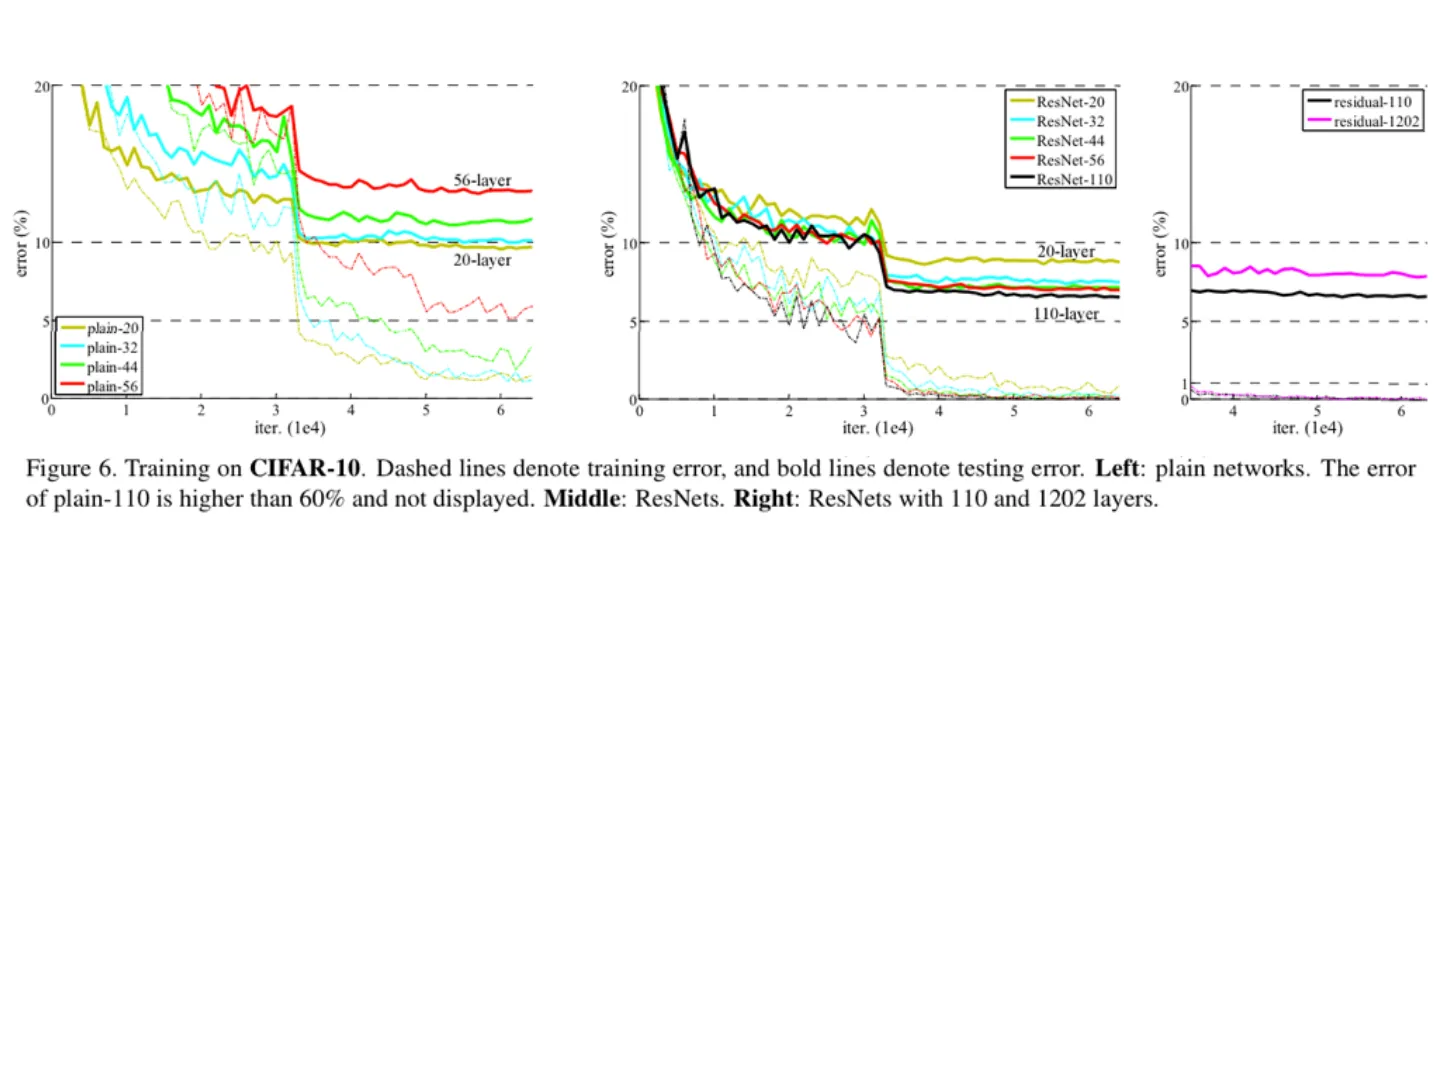
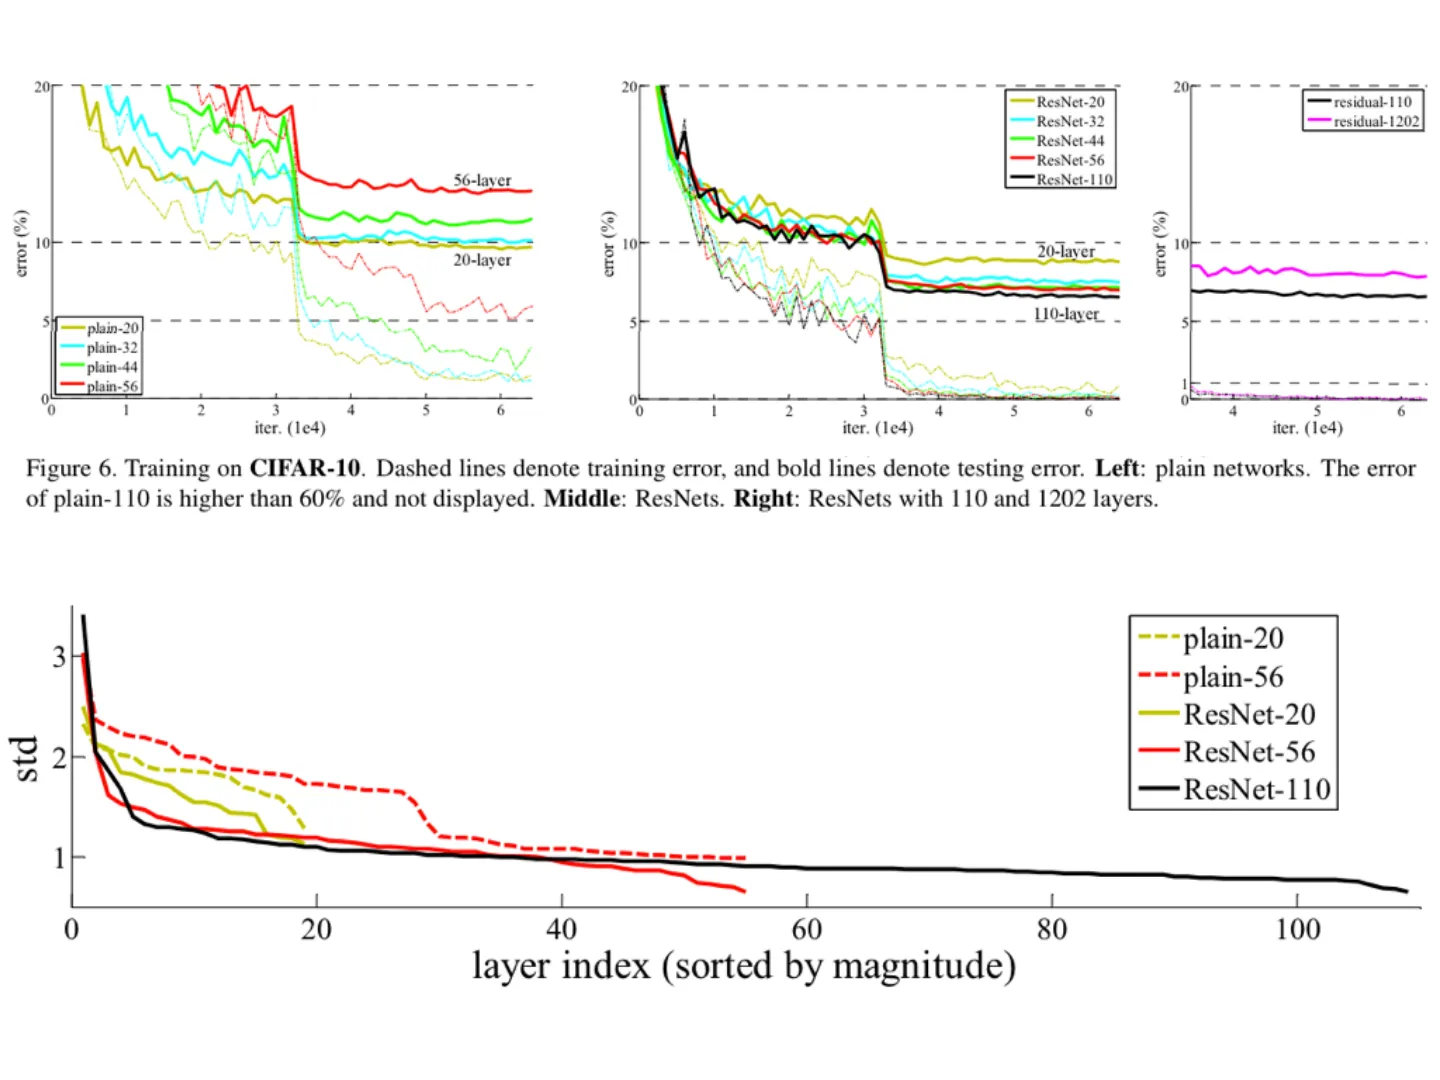
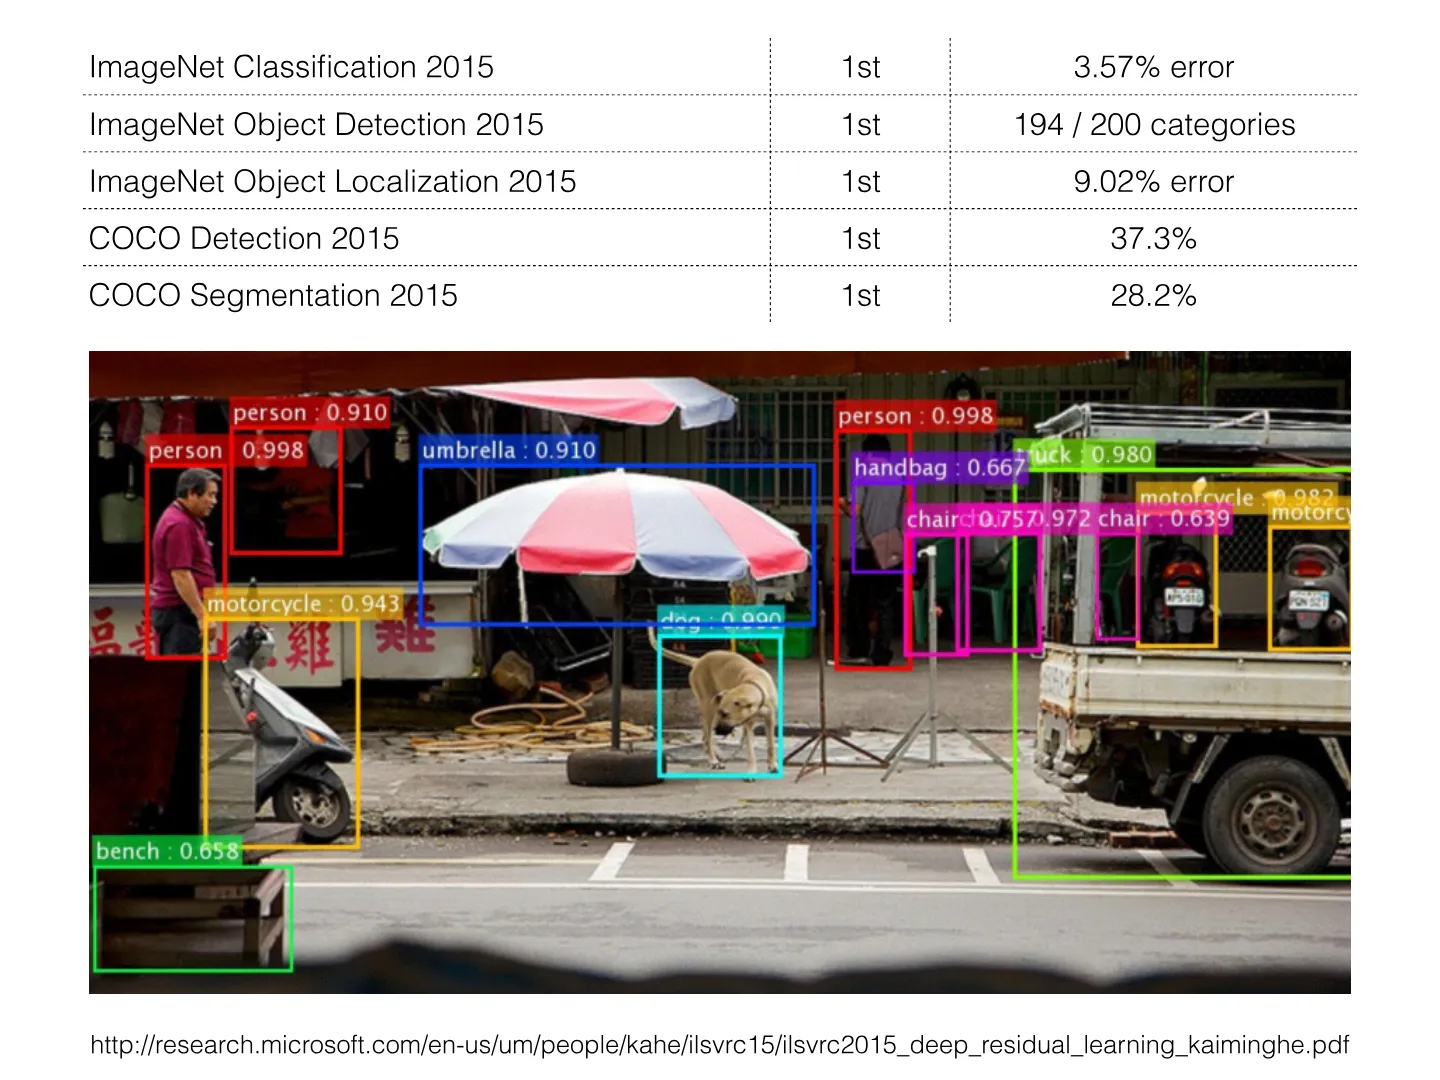
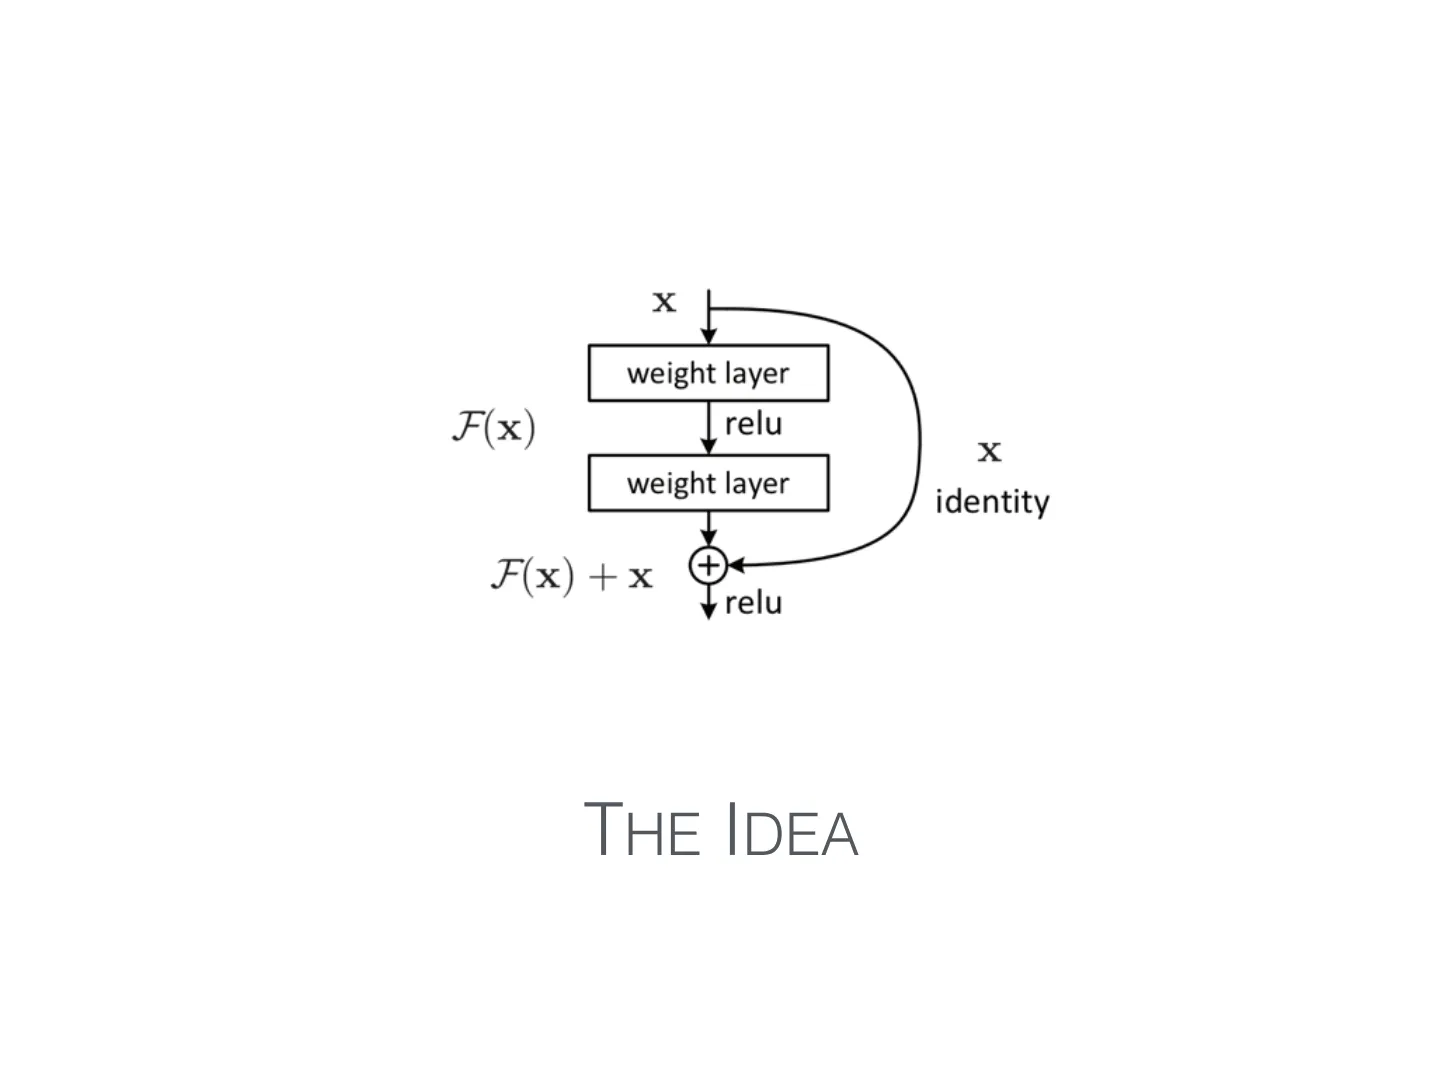
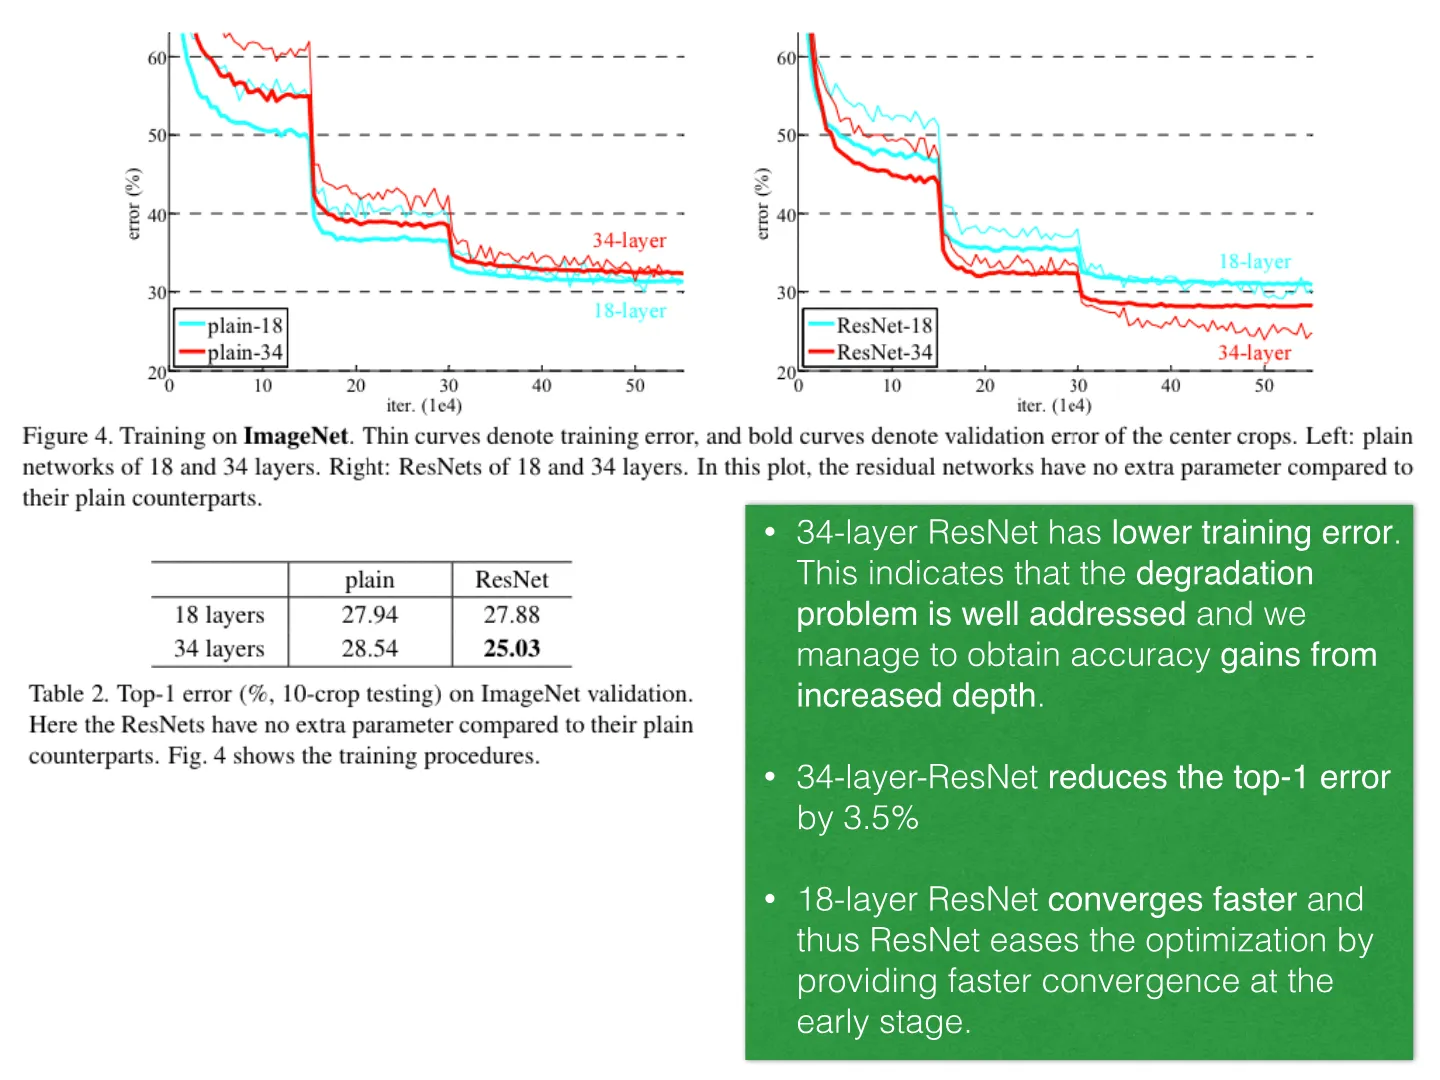
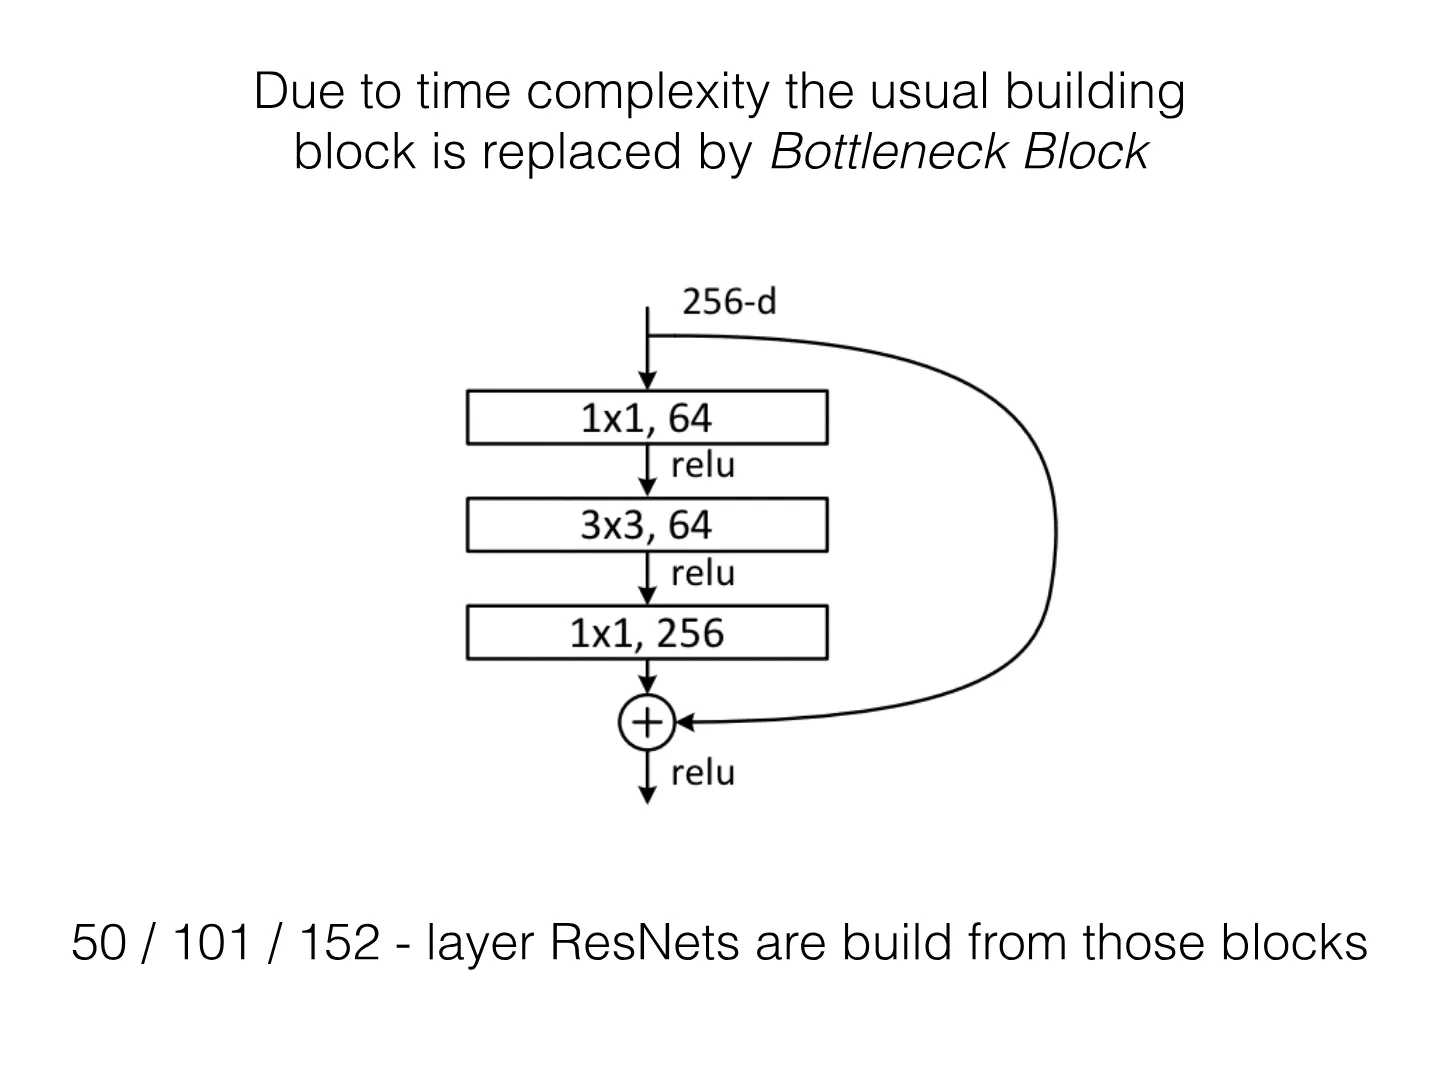
Slide 1 of 44: Article overview by Ilya Kuzovkin K. He, X. Zhang, S. Ren and J. Sun Microsoft Research Computational Neuroscience Seminar University of Tartu 2016 Deep Residual Learning for Image Recognition ILSVRC 2015 MS COCO 2015 WINNERSlide 2 of 44: THE IDEASlide 3 of 44: 1000 classesSlide 4 of 44: 2012 8 layers 15.31% errorSlide 5 of 44: 2012 8 layers 15.31% error 2013 9 layers, 2x params 11.74% errorSlide 6 of 44: 2012 8 layers 15.31% error 2013 2014 9 layers, 2x params 11.74% error 19 layers 7.41% errorSlide 7 of 44: 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error ?Slide 8 of 44: 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error Is learning better networks as easy as stacking more layers ? ?Slide 9 of 44: ? 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error Is learning better networks as easy as stacking more layers ? Vanishing / exploding gradientsSlide 10 of 44: ? 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error Is learning better networks as easy as stacking more layers ? Vanishing / exploding gradients Normalized initialization & intermediate normalizationSlide 11 of 44: ? 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error Is learning better networks as easy as stacking more layers ? Vanishing / exploding gradients Normalized initialization & intermediate normalization Degradation problemSlide 12 of 44: Degradation problem “with the network depth increasing, accuracy gets saturated”Slide 13 of 44: Not caused by overfitting: Degradation problem “with the network depth increasing, accuracy gets saturated”Slide 14 of 44: Conv Conv Conv Conv Trained Accuracy X% TestedSlide 15 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Tested TestedSlide 16 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Tested TestedSlide 17 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Conv Conv Conv Conv Conv Conv Conv Conv Trained Tested Tested TestedSlide 18 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Conv Conv Conv Conv Conv Conv Conv Conv Trained Worse! Tested Tested TestedSlide 19 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Conv Conv Conv Conv Conv Conv Conv Conv Trained Worse! Tested Tested Tested “Our current solvers on hand are unable to find solutions that are comparably good or…Slide 20 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Conv Conv Conv Conv Conv Conv Conv Conv Trained Worse! Tested Tested Tested “Our current solvers on hand are unable to find solutions that are comparably good or…Slide 21 of 44: Conv Conv Conv Conv Trained Accuracy X% Conv Conv Conv Conv Identity Identity Identity Identity Same performance Conv Conv Conv Conv Conv Conv Conv Conv Trained Worse! Tested Tested Tested “Our current solvers on hand are unable to find solutions that are comparably good or…Slide 22 of 44: Add explicit identity connections and “solvers may simply drive the weights of the multiple nonlinear layers toward zero ” is the true function we want to learnSlide 23 of 44: Add explicit identity connections and “solvers may simply drive the weights of the multiple nonlinear layers toward zero ” is the true function we want to learn Let’s pretend we want to learn instead.Slide 24 of 44: Add explicit identity connections and “solvers may simply drive the weights of the multiple nonlinear layers toward zero ” is the true function we want to learn Let’s pretend we want to learn instead. The original function is thenSlide 25 of 44Slide 26 of 44: Network can decide how deep it needs to be…Slide 27 of 44: Network can decide how deep it needs to be… “The identity connections introduce neither extra parameter nor computation complexity”Slide 28 of 44: 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error ?Slide 29 of 44: 2012 8 layers 15.31% error 2013 2014 2015 9 layers, 2x params 11.74% error 19 layers 7.41% error 152 layers 3.57% errorSlide 30 of 44: EXPERIMENTS AND DETAILSSlide 31 of 44: • Lots of convolutional 3x3 layers • VGG complexity is 19.6 billion FLOPs 34-layer-ResNet is 3.6 bln. FLOPsSlide 32 of 44: • Lots of convolutional 3x3 layers • VGG complexity is 19.6 billion FLOPs 34-layer-ResNet is 3.6 bln. FLOPs ! • Batch normalization • SGD with batch size 256 • (up to) 600,000 iterations • LR 0.1 (divided by 10 when error plateaus) • Momentum 0.9 • No dropout • Weight decay…Slide 33 of 44: • Lots of convolutional 3x3 layers • VGG complexity is 19.6 billion FLOPs 34-layer-ResNet is 3.6 bln. FLOPs ! • Batch normalization • SGD with batch size 256 • (up to) 600,000 iterations • LR 0.1 (divided by 10 when error plateaus) • Momentum 0.9 • No dropout • Weight decay…Slide 34 of 44: • 34-layer ResNet has lower training error . This indicates that the degradation problem is well addressed and we manage to obtain accuracy gains from increased depth .Slide 35 of 44: • 34-layer ResNet has lower training error . This indicates that the degradation problem is well addressed and we manage to obtain accuracy gains from increased depth . ! • 34-layer-ResNet reduces the top-1 error by 3.5%Slide 36 of 44: • 34-layer ResNet has lower training error . This indicates that the degradation problem is well addressed and we manage to obtain accuracy gains from increased depth . ! • 34-layer-ResNet reduces the top-1 error by 3.5% ! • 18-layer ResNet converges faster and thus ResNet eases…Slide 37 of 44: GOING DEEPERSlide 38 of 44: Due to time complexity the usual building block is replaced by Bottleneck Block 50 / 101 / 152 - layer ResNets are build from those blocksSlide 39 of 44Slide 40 of 44Slide 41 of 44: ANALYSIS ON CIFAR-10Slide 42 of 44Slide 43 of 44Slide 44 of 44: ImageNet Classification 2015 1st 3.57% error ImageNet Object Detection 2015 1st 194 / 200 categories ImageNet Object Localization 2015 1st 9.02% error COCO Detection 2015 1st 37.3% COCO Segmentation 2015 1st 28.2%…
1 / 44

Paper overview: “Deep Residual Learning for Image Recognition”

A talk given at the Computational Neuroscience Seminar @ University of Tartu. We discuss the idea behind the deep neural network that won ILSVRC (ImageNet) 2015 and COCO 2015 Image competitions.

Download PDF