The Concept of Conjugate Gradient Descent in Python
While reading “An Introduction to the Conjugate Gradient Method Without the Agonizing Pain” I decided to boost my understanding by repeating the story told there in Python. So far I’ve gone through the explanation of the basic concept behind the idea of CG. You can download the notebook here to play with parameters and the code.
Introduction
In this example we follow An Introduction to the Conjugate Gradient Method Without the Agonizing Pain and demonstrate a few concepts in Python. I shamelessly quote the original document in a few places. References to equations and figures are given in terms of the original document.
import numpy as np
import matplotlib.pyplot as plt
from mpl_toolkits.mplot3d import Axes3D
import itertools
A 2D example we will work with:
A = np.matrix([[3.0, 2.0], [2.0, 6.0]])
b = np.matrix([[2.0], [-8.0]])  # we will use the convention that a vector is a column vector
c = 0.0
The quadratic form:
def f(x, A, b, c):
    return float(0.5 * x.T * A * x - b.T * x + c)
Evaluate the function on a small grid and draw it:
def bowl(A, b, c):
    fig = plt.figure(figsize=(10,8))
    qf = fig.gca(projection='3d')
    size = 20
    x1 = list(np.linspace(-6, 6, size))
    x2 = list(np.linspace(-6, 6, size))
    x1, x2 = np.meshgrid(x1, x2)
    zs = np.zeros((size, size))
    for i in range(size):
        for j in range(size):
            x = np.matrix([[x1[i,j]], [x2[i,j]]])
            zs[i,j] = f(x, A, b, c)
    qf.plot_surface(x1, x2, zs, rstride=1, cstride=1, cmap=cm.coolwarm, linewidth=0)
    fig.show()
return x1, x2, zsx1, x2, zs = bowl(A, b, c)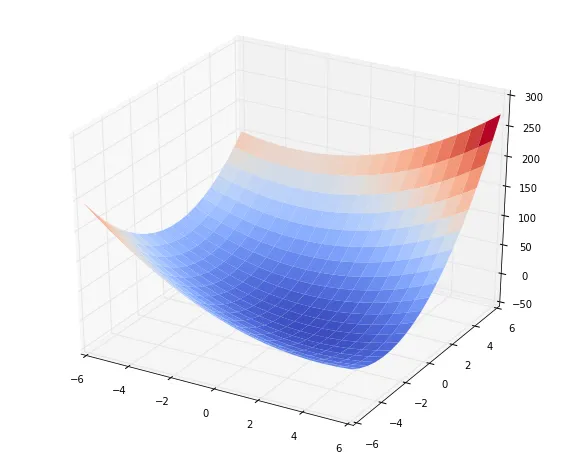
def contoursteps(x1, x2, zs, steps=None):
    fig = plt.figure(figsize=(6,6))
    cp = plt.contour(x1, x2, zs, 10)
    plt.clabel(cp, inline=1, fontsize=10)
    if steps is not None:
        steps = np.matrix(steps)
        plt.plot(steps[:,0], steps[:,1], '-o')
    fig.show()
Contour plot of the same quadratic form:
contoursteps(x1, x2, zs)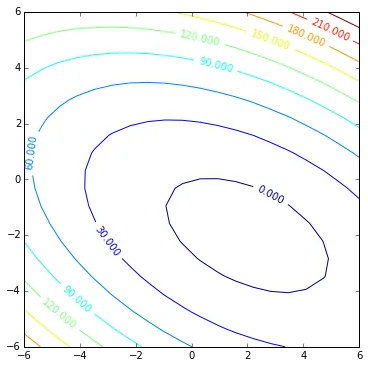
The Method of Steepest Descent
The algorithm is implemented following (with slight changes) the pseudocode from Appendix B1 of the tutorial.
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10
eps = 0.01
r = b - A * x
delta = r.T * r
delta0 = delta
while i < imax and delta > eps**2 * delta0:
    alpha = float(delta / (r.T * (A * r)))
    x = x + alpha * r
    steps.append((x[0,0], x[1,0]))  # store steps for future drawing
    r = b - A * x
    delta = r.T * r
    i += 1
Here we can follow its steps:
contoursteps(x1, x2, zs, steps)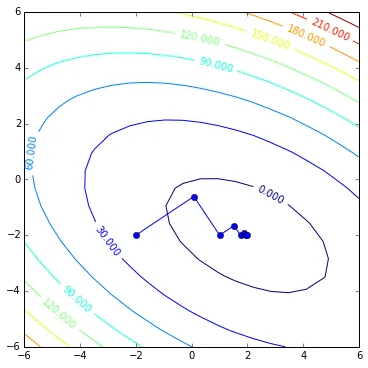
Let us have a look at one iteration
We visualize various thingies that play a role in there. It will help to gain the intuition of how it goes. First we initialize the starting point and a few parameters:
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10
eps = 0.01
The first object to look at is the residual, denoted by r in the code; let’s see what exactly it stands for:
print 'b:\n', b
print 'A:\n', A
print 'x:\n', x
r = b - A * x
print 'r:\n', r
contoursteps(x1, x2, zs, None)
plt.plot([0, r[0, 0] * 0.5], [0, r[1, 0] * 0.5], 'g')
plt.show()
b:
[[ 2.]
[-8.]]
A:
[[ 3. 2.]
[ 2. 6.]]
x:
[[-2.]
[-2.]]
r:
[[ 12.]
[ 8.]]
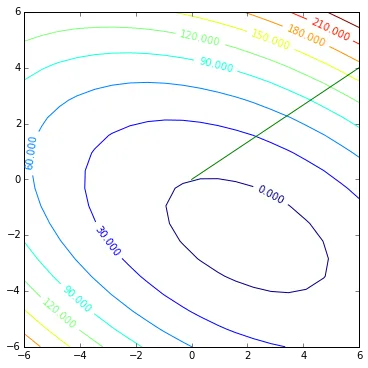
Observe now that residual actually means direction of steepest descent. The vector also has a magnitude, as you can see, but since it does not directly provide any useful information (other than some notion of how far away we are from the desired solution) we will not dig into it.
print '||r||^2 =', np.linalg.norm(r)**2
delta = r.T * r
print 'r.T * r = ',  delta
delta0 = delta
||r||^2 = 208.0
r.T * r = [[ 208.]]
#while i < imax and delta > eps**2 * delta0:We now have the direction; the next question is how far along that direction we need to go?. The procedure to answer that is called line search and its task is to take the direction and find the minimal point of the parabola formed by this line and the quadratic bowl. We need to estimate alpha which will tell how far along the line we should move. The equation to get alpha in our code is:
alpha = float(delta / (r.T * (A * r))),
which corresponds to
in the tutorial. Let me repeat the derivation from the tutorial to see why this will give the alpha we want (please refer to Figure 6 of the tutorial to agree with the initial premise ):
alpha = float(delta / (r.T * A * r))Now we know how far to go along r and we update our solution x:
x = x + alpha * r
contoursteps(x1, x2, zs, [(-2, -2), (x[0, 0], x[1, 0])])
plt.plot([0, r[0, 0] * 0.5], [0, r[1, 0] * 0.5], 'g')
plt.show()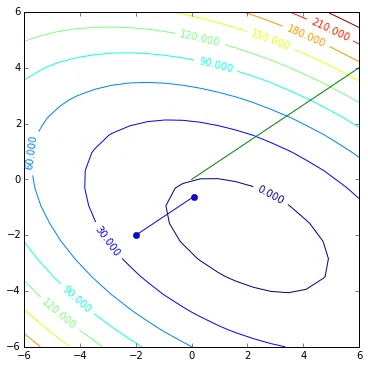
And now the loop repeats: we are in some location, we compute the residual, get the direction:
r = b - A * x
contoursteps(x1, x2, zs, [(-2, -2), (x[0, 0], x[1, 0])])
plt.plot([0, r[0, 0]], [0, r[1, 0]], 'g')
[<matplotlib.lines.Line2D at 0x10b9a2990>]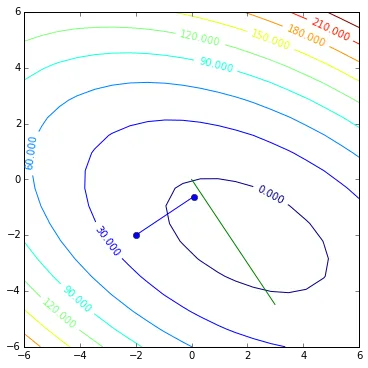
Update delta and the iteration counter, and we are ready to perform the next line search and make the next step
delta = r.T * r
i += 1
Gradient descent
It might be interesting for you to compare steepest descent to what we usually refer to as gradient descent where instead of performing line search we fix alpha (learning rate) to some fixed parameter:
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10000
eps = 0.01
alpha = 0.12  # play with this value to see how it affects the optimization process, try 0.05, 0.27 and 0.3
r = b - A * x
delta = r.T * r
delta0 = delta
while i < imax and delta > eps**2 * delta0:
    x = x + alpha * r
    steps.append((x[0,0], x[1,0]))  # store steps for future drawing
    r = b - A * x
    delta = r.T * r
i += 1contoursteps(x1, x2, zs, steps)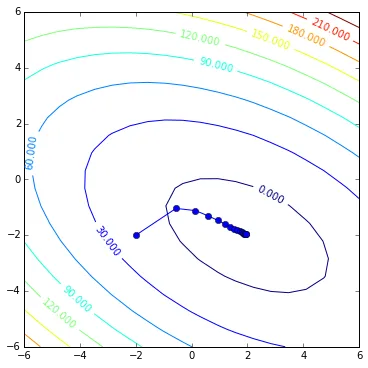
Change the alpha parameter to see what happens when your learning rate is too low or too high.
The Method of Conjugate Directions
As you have seen, in the steepest descent method the algorithm makes steps in the same direction several times. Here’s an idea: let’s pick a set of orthogonal search directions so that if we take exactly one step of the right length in each of those directions we will reach the minimum.
Conjugacy
First we introduce the notion of A-orthogonal vectors, where A is the matrix with coefficients from our original equation .
Take a round quadratic bowl:
Around = np.matrix([[1, 0],[0, 1]])
bround = np.matrix([[0],[0]])
cround = 0
x1, x2, zs = bowl(Around, bround, cround)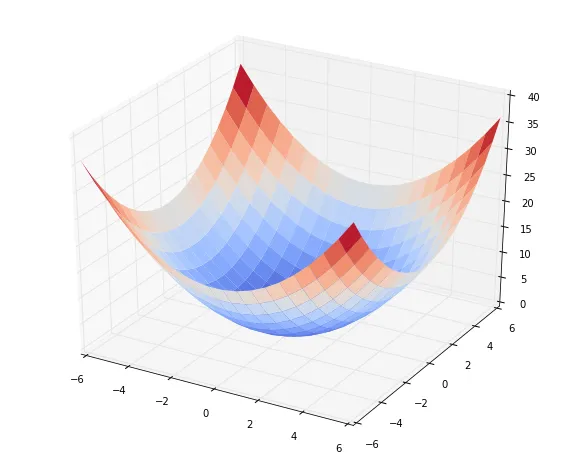
Now take two orthogonal vectors and draw them:
va = np.matrix([[2],[2]])
vb = np.matrix([[2],[-2]])
contoursteps(x1, x2, zs, [(va[0,0],va[1,0]),(0,0),(vb[0,0],vb[1,0])])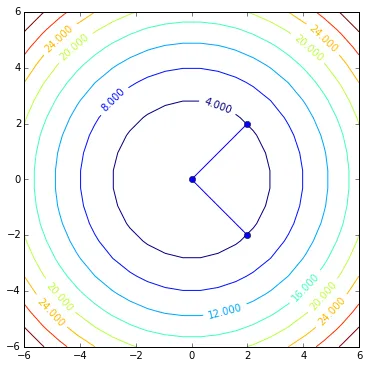
Now instead of the identity matrix take a matrix that has the Y axis scaled up 2 times.
Ascaled = np.matrix([[1, 0],[0, 2]])
bscaled = np.matrix([[0],[0]])
cscaled = 0
x1, x2, zs = bowl(Ascaled, bscaled, cscaled)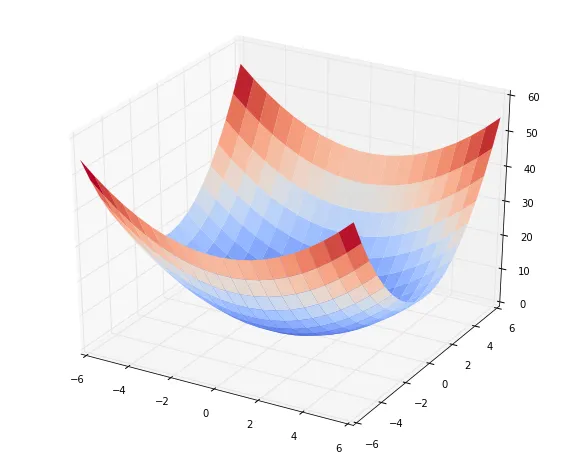
To counter the scale of the matrix we scale the X components of the vectors 2 times and draw them:
va = np.matrix([[2],[np.sqrt(2)]])
vb = np.matrix([[2],[-np.sqrt(2)]])
contoursteps(x1, x2, zs, [(va[0,0],va[1,0]),(0,0),(vb[0,0],vb[1,0])])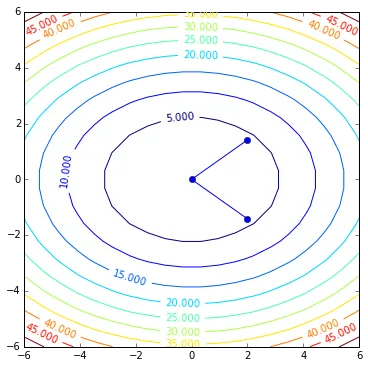
As you can see, those vectors are not orthogonal:
float(va.T * vb)1.9999999999999996but they are -orthogonal under the matrix Ascaled:
float(va.T * Ascaled * vb)-8.881784182001252e-16Vectors and are -orthogonal or conjugate iff
The intuition is to imagine that if you stretch the contour plot so that the contours are circles and two vectors become orthogonal, then they are -orthogonal.
Ok, well, why would we care about those? Imagine that you need to find the solution in a non-distorted circular 2D bowl:
Around = np.matrix([[1, 0],[0, 1]])
bround = np.matrix([[0],[0]])
cround = 0
x1, x2, zs = bowl(Around, bround, cround)
then you could achieve your solution in two steps using usual steepest descent:
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10
eps = 0.01
r = bround - np.matrix([[1, 0],[0, 0]]) * x  # replaced Around with this to force residual to be parallel to X axis
delta = r.T * r
delta0 = delta
while i < imax and delta > eps**2 * delta0:
    alpha = float(delta / (r.T * (Around * r)))
    x = x + alpha * r
    steps.append((x[0,0], x[1,0]))  # store steps for future drawing
    r = bround - Around * x
    delta = r.T * r
i += 1contoursteps(x1, x2, zs, steps)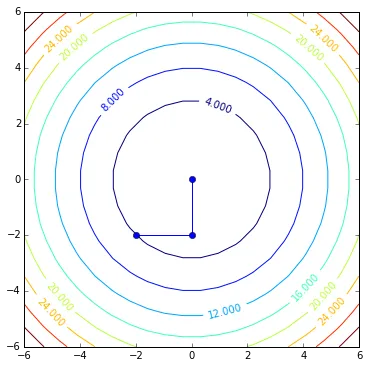
That would be cool, wouldn’t it? Unfortunately, optimization problems do not always have a circular bowl error surface. So if we use conjugate directions instead of orthogonal ones, then it is as if we are solving our problem on a circular bowl surface. All that is needed now is a set of conjugate (-orthogonal) directions; fortunately, we can find those using the conjugate Gram-Schmidt process.
Gram-Schmidt Conjugation
We will need conjugate directions. First we take linearly independent vectors. For example, the residuals we used in the steepest descent will do nicely, because we selected each next residual to be orthogonal to the previous search directions (Equation 39). Right now I will only mention that the Gram-Schmidt process is the method we will use and later you will see how it works and what it does.
The Method of Conjugate Gradients
Let me generate the original error surface again.
x1, x2, zs = bowl(A, b, c)
And follow the pseudocode in B2 to implement the CG method.
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10
eps = 0.01
r = b - A * x
d = r
deltanew = r.T * r
delta0 = deltanew
while i < imax and deltanew > eps**2 * delta0:
    alpha = float(deltanew / float(d.T * (A * d)))
    x = x + alpha * d
    steps.append((x[0, 0], x[1, 0]))
    r = b - A * x
    deltaold = deltanew
    deltanew = r.T * r
    #beta = -float((r.T * A * d) / float(d.T * A * d))
    beta = float(deltanew / float(deltaold))
    d = r + beta * d
i += 1contoursteps(x1, x2, zs, steps)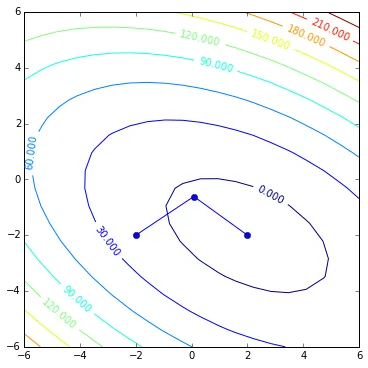
It works! And it did reach the solution in 2 steps!
If you compare it to the steepest descent, you will see that not much has changed; the only conceptually new lines are
beta = float(deltanew / deltaold)
d = r + beta * d
let’s see what they do.
The initialization is very similar; we now have d instead of r to show the direction of the descent.
x = np.matrix([[-2.0],[-2.0]])
steps = [(-2.0, -2.0)]
i = 0
imax = 10
eps = 0.01
r = b - A * x
d = r
deltanew = r.T * r
delta0 = deltanew
#while i < imax and deltanew > eps**2 * delta0:
Here we step into the iteration of the main loop and it also looks quite familiar. I will not draw the first step since it looks exactly like the first step of the steepest descent. Only starting from the second step will we have a restricting condition: the direction of our second step will have to be conjugate to the direction of the first step. But we will worry about that later, right now we boldly make our first step in the direction of the steepest descent.
alpha = float(deltanew / float(d.T * (A * d)))
x = x + alpha * d
steps.append((x[0, 0], x[1, 0]))
The first step is done and now it is time to figure out the next direction.
r = b - A * xcontoursteps(x1, x2, zs, [(-2, -2), (x[0,0],x[1,0])])
plt.plot([0, r[0, 0]], [0, r[1, 0]])
plt.show()
This would be the direction steepest descent would take us, but this time we are bound by the rule that our next step should be A-orthogonal (conjugate) to the first step. And currently
d.T * A * rmatrix([[-167.25333333]])that is not the case. So here is what we are going to do:
deltaold = deltanew
deltanew = r.T * r
beta = float(deltanew / float(deltaold))
this is a new variable, but before going into the details of what it represents let’s see what it does:
oldd = d  # this is needed for future demonstration, not relevant to the algorithm
d = r + beta * d
and our new direction now looks like this
contoursteps(x1, x2, zs, [(-2, -2), (x[0,0],x[1,0])])
plt.plot([0,d[0,0]], [0, d[1,0]])  # new direction
plt.plot([0,r[0,0]], [0, r[1,0]])  # old direction (residual)
plt.show()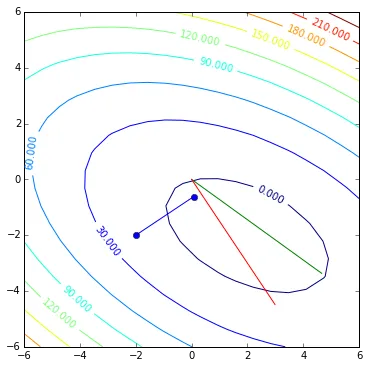
and it also satisfies the condition of conjugacy
oldd.T * A * dmatrix([[ 0.]])So let us go into the math and see how steered us to the conjugate direction.
The final equation we use to obtain is
now let us see how we get that from the Gram-Schmidt process and the initial idea of building conjugate directions from the residuals.
So we have linearly independent vectors we call residuals. And we want to get conjugate vectors we call directions. To construct we take and subtract from it the non-conjugate components of all previous vectors (see Figure 24).
For it is easy: , and for all the next ones it can be computed as
where would indicate how much of each previous direction should be subtracted ( will be a negative coefficient) from . For the particular direction we compute it as follows. First we multiply the whole equation by :
Next we observe that we know that because of -orthogonality. So all addends, except for the are 0. And the left-hand side of the equation we set to 0, because this is what we want to achieve:
and from that
That is already computable and in our code would look like
beta = -float((r.T * A * d) / float(d.T * A * d))but we can simplify it further and avoid doing matrix multiplications.
Note that (page 6) and from that we can get a recurrence for the residual
we multiply it by
Since the residuals are othogonal we know and we can leave it out:
Now we take an equation for and put it in:
We also had an equation for :
We apply it on , replace and get
The final touch is to use (see equations 40 and 42) we get the desired
To remind you what it was: shows how much of the direction we should take to keep -orthogonal (conjugate) to .
Now we increase the iteration counter and continue to the next (in this particular 2D case, final) iteration.
i += 1where we will decide on how far we should go in this direction and happily reach the minimum point:
alpha = float(deltanew / float(d.T * (A * d)))
x = x + alpha * d
steps.append((x[0, 0], x[1, 0]))
contoursteps(x1, x2, zs, steps)
plt.plot([0,d[0,0]], [0, d[1,0]])
plt.show()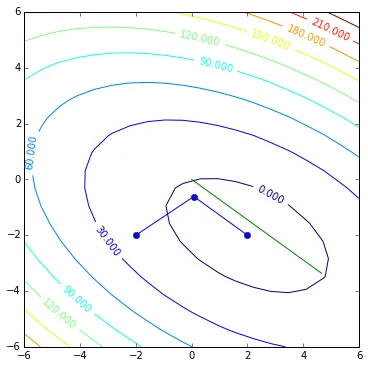
All that is fine, you say, but looking for a minimum point of a quadratic form isn’t what you usually need in practice. The next piece of this story will cast light on that.